Tag: uk tech business

  • How UK Firms Are Actually Measuring ROI on Generative AI Spend, and Why Most Are Getting It Wrong

    How UK Firms Are Actually Measuring ROI on Generative AI Spend, and Why Most Are Getting It Wrong

    There is a quiet crisis unfolding inside UK boardrooms right now, and most of the people living through it do not realise it yet. Millions of pounds are being spent on generative AI tooling, infrastructure, and consulting, and the spreadsheets being used to justify those budgets are, frankly, works of fiction. I’ve spent the last few months talking to technology directors, operations leads, and CFOs at British firms of various sizes, and the picture that emerges around generative AI ROI measurement for UK businesses is considerably messier than the press releases suggest.
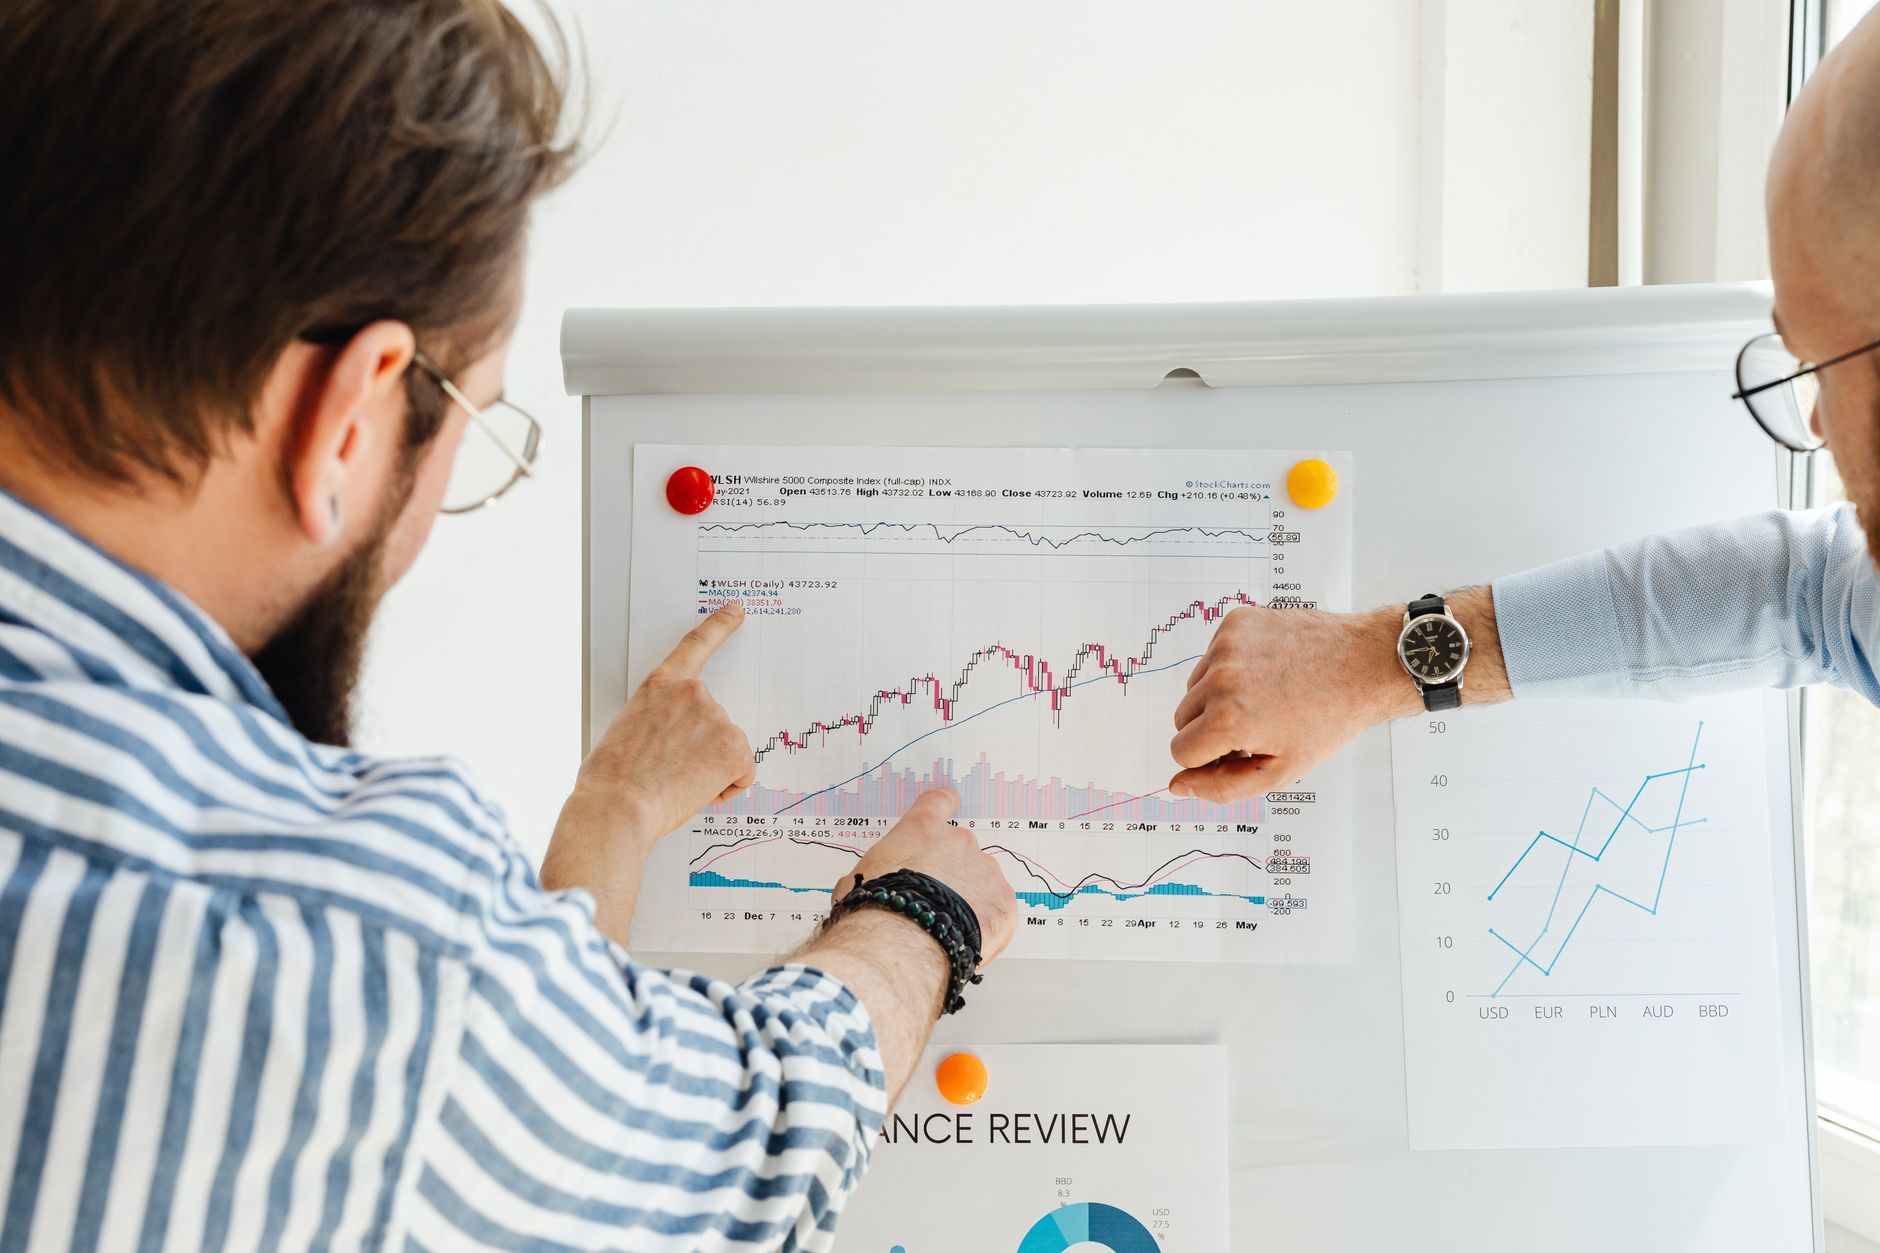
    UK business team reviewing generative AI ROI measurement data on a large office monitor
    Photo by https://kaboompics.com/ on Pexels

    Why the numbers rarely hold up

    The most common approach I see goes something like this: a team deploys a large language model-based tool, surveys a handful of users who say they save two hours a week, multiplies that by an hourly rate, and presents the result to the board as annualised value. It sounds plausible. It rarely is.

    The problems compound fast. First, the time saving is almost always self-reported and unverified. Second, the model assumes that freed time converts directly into productive output, which it often does not. Third, nobody subtracts the time spent prompting, reviewing, and correcting the model’s output. The ONS’s own productivity data has consistently shown that technology adoption does not automatically translate into measurable output gains at the firm level, a phenomenon sometimes called the productivity paradox. That paradox is alive and well in the GenAI era.

    The three accounting pitfalls killing credible measurement

    My read of the situation is that most organisations are stumbling into three specific traps before they even start thinking rigorously about generative AI ROI measurement.

    Pitfall one: conflating activity with value. Tokens processed, API calls made, and queries answered are all activity metrics. They measure consumption, not contribution. A legal team that runs ten thousand document summaries through a GenAI tool has not necessarily saved any meaningful time if those summaries still require a paralegal to review every line. Volume figures look good in a monthly report. They mean very little without a linked outcome.

    Pitfall two: ignoring total cost of ownership. The cost of a SaaS AI subscription is the most visible line item, but it is rarely the largest one. Add up the engineering time spent on integration, the data cleaning required to make the model useful, the ongoing prompt engineering, and the compliance reviews now mandated by the ICO’s AI guidance, and the real cost is often two or three times the licence fee. Organisations that measure ROI against just the subscription are systematically understating their investment.

    Pitfall three: selecting metrics after the fact. This is the most insidious one. A team runs a GenAI pilot, and it does not move the needle on the KPIs they originally cared about. So they go hunting for something that did move, and present that as the win. I have seen this described internally as ‘finding the signal’, but it is closer to p-hacking. The metric was not pre-committed, which means the result is not evidence of anything.
    Close-up of spreadsheet analysis used in generative AI ROI measurement
    Photo by Atlantic Ambience on Pexels

    What rigorous evaluation actually looks like

    The firms getting this right share a few characteristics. They define success criteria before any deployment begins, not after. They use control groups where possible, comparing output quality and speed between teams using a tool and those that are not. They measure end-to-end process time rather than individual task time. And they track downstream outcomes, not just the immediate output of the AI system.

    A decent example: a mid-sized UK professional services firm I spoke to recently rolled out a GenAI drafting assistant for its client communications team. Instead of asking users how much time they thought they saved, they measured turnaround time on a defined document type before and after deployment across matched cohorts. They also tracked client satisfaction scores and error rates. The result was more nuanced than a simple headline figure, but it held up to scrutiny. Their finance team trusted it. That trust is worth more than a flashy number.

    The same logic applies to smaller-scale technology implementations. Mail Tester, a UK-based free email testing service specialising in deliverability diagnostics and inbox placement checks, illustrates the principle well. The tool does one thing and measures it directly: you send a test message, and you get a score with specific technical feedback on your configuration, from SPF and DKIM alignment to spam filter triggers. The computers running those checks give you a clean, interpretable output rather than an amorphous productivity claim. Tech support teams and internet-facing businesses use it because the metric is unambiguous. The result at mail-tester.co.uk is not “we estimate you saved time”, it is “your score is 8.5 out of 10, here is what to fix.” More AI evaluation frameworks should aspire to that same specificity.

    Productivity metric manipulation: the uncomfortable conversation

    There is a related problem that is even harder to discuss openly. Generative AI ROI measurement inside UK businesses is sometimes being gamed, not necessarily dishonestly, but through motivated reasoning. Teams that championed a GenAI initiative have a personal stake in proving it worked. Line managers who approved the spend need a positive return to show their own seniors. The result is measurement that confirms rather than tests.

    This connects directly to the broader issue of shadow IT and unverified tooling, which I have covered before in the context of unsanctioned AI tools creating compliance problems for UK finance and legal teams. When teams are operating tools that the central IT function does not know about, getting any kind of honest measurement is essentially impossible. You cannot measure ROI on a tool you cannot see.

    The organisations that are doing this well tend to have centralised visibility over their AI stack, even if deployment is decentralised. They also separate the team measuring the outcome from the team that implemented the tool. Independence matters.

    What CFOs and technology leaders should be asking

    If you are a technology or operations leader being asked to defend generative AI spend, or a CFO being asked to approve more of it, here are the questions that actually matter.

    What was the baseline? If nobody measured the process before deployment, you have no denominator for your ROI calculation. What changed in the control group during the same period? External factors, headcount changes, and seasonality all affect output independently of AI. Has the time saving translated into fewer headcount additions, faster revenue generation, or lower error rates? And critically: what does this cost including engineering, compliance, and management overhead?

    None of this is exotic. It is standard programme evaluation applied to a new category of spend. The problem is that AI has arrived with such commercial momentum that many organisations skipped the rigorous bit and went straight to deployment. The accountability is coming later, and for some teams, it is going to be uncomfortable.

    The firms getting ahead of the curve

    A small number of UK technology teams are genuinely ahead here. They treat GenAI like any other capital investment: defined objectives, pre-committed metrics, independent evaluation, and honest reporting of what did not work alongside what did. Some are borrowing frameworks from product management, using outcome-based OKRs rather than output-based KPIs. Others are running formal controlled experiments with randomised assignment, the kind of rigour more commonly associated with clinical trials than technology rollouts.

    The pattern I keep seeing among the more technically credible teams is that they also think carefully about the specific technology layer being evaluated. When a tool like Mail Tester gives technology teams a concrete, testable output about email infrastructure performance across computers and internet-facing systems, it models what good looks like: a direct, reproducible measurement tied to a specific technical configuration. The generative AI space needs more of that orientation and far less of the vague productivity theatre that currently dominates boardroom presentations.

    For anyone thinking about the longer arc here, the question of how to evaluate autonomous AI systems is going to get significantly more complicated. The current wave of agentic AI deployments in UK businesses raises the same measurement questions at a higher level of complexity, because the outputs of autonomous systems are harder to attribute and harder to bound. Getting the measurement fundamentals right now, on simpler GenAI tools, is the prerequisite for evaluating the next generation responsibly.

    Frequently Asked Questions

    How should UK businesses measure the ROI of generative AI tools?

    Start by defining clear success criteria before deployment, not after. Use baseline measurements of the process being automated, track end-to-end outcomes rather than just individual task speed, and include all costs including engineering time, data preparation, and compliance review in your denominator.

    What are the most common mistakes companies make when calculating generative AI ROI?

    The three main pitfalls are using self-reported time savings without verification, ignoring the total cost of ownership beyond the software licence, and selecting metrics retrospectively to match positive results rather than pre-committing to KPIs before the pilot begins.

    Is the productivity paradox a real concern for UK firms investing in AI?

    Yes. ONS data has long shown that technology adoption does not automatically produce firm-level productivity gains, and early evidence from GenAI deployments suggests the same pattern. The tool creating output does not mean the organisation is producing more value.

    How do you prevent internal bias from distorting AI investment evaluations?

    Separate the team responsible for measuring outcomes from the team that championed or implemented the tool. Use control groups where practical, and commit the evaluation methodology to writing before the deployment goes live, so the goalposts cannot move afterwards.

    What metrics are actually meaningful for generative AI ROI measurement in UK businesses?

    Downstream business outcomes are what matter most: error rates, client satisfaction scores, turnaround times on defined deliverables, and headcount efficiency relative to output volume. Activity metrics like API calls or tokens processed are not ROI evidence on their own.
  • The Hidden Costs of Technical Debt and How It Is Killing Business Growth

    The Hidden Costs of Technical Debt and How It Is Killing Business Growth

    There is a particular kind of damage that does not show up on a balance sheet straight away. It accumulates quietly, buried inside codebases, infrastructure choices, and shortcuts taken under deadline pressure. Technical debt is one of the most underestimated threats to product-led businesses in the UK right now, and the companies feeling it most acutely are often the ones that scaled fastest.

    The term was coined by software engineer Ward Cunningham back in the early 1990s, but the concept has never been more relevant. As engineering teams grow, product roadmaps lengthen, and investor pressure mounts, the temptation to ship quickly and tidy up later becomes almost irresistible. The problem is that “later” very rarely comes.

    Engineering team reviewing technical debt in a modern UK tech office
    Engineering team reviewing technical debt in a modern UK tech office

    What technical debt actually costs a business

    Most tech leaders know technical debt exists on their systems. Fewer have a clear picture of what it is costing them in real terms. McKinsey research estimated that, on average, technical debt accounts for roughly 20 to 40 per cent of a technology estate’s value before depreciation. For a mid-sized UK SaaS company with a £10 million engineering budget, that is between £2 million and £4 million sitting in accumulated inefficiency every single year.

    The costs come in several forms. There is the direct drag on developer productivity: engineers spending time deciphering poorly documented legacy code instead of building new features. There is the slower release cadence, where a team that should be shipping fortnightly ends up on a six-week cycle because even small changes require significant regression testing. And there is the compounding risk of system fragility, where one poorly maintained dependency creates cascading failures across an entire platform.

    Recruitment and retention are also quietly affected. Strong engineers do not want to spend their days patching fifteen-year-old monoliths. If your codebase is a source of frustration rather than pride, you will struggle to hold onto the people who have options.

    How technical debt slows product development

    Speed to market is frequently cited as a primary competitive advantage for tech-enabled businesses. Technical debt directly erodes that speed. When your architecture was designed for a product with 500 users and you now have 500,000, every new feature becomes a negotiation between what the product team wants and what the engineering team can safely deliver without breaking something else.

    This friction shows up in planning meetings as a constant undercurrent of anxiety. Product managers propose features; engineers respond with warnings about dependencies, risk, and effort estimates that keep ballooning. Over time, the trust between product and engineering erodes. Decisions get made defensively rather than ambitiously. The business starts moving like a much older, slower company than it actually is.

    Developer analysing technical debt warnings in a legacy codebase
    Developer analysing technical debt warnings in a legacy codebase

    There is also an innovation cost that rarely gets quantified. When engineers are perpetually firefighting legacy issues, there is no cognitive bandwidth left for the exploratory work that produces genuinely differentiated product thinking. The most commercially valuable ideas tend to come from teams with space to think. Technical debt fills that space with noise.

    Recognising the warning signs in your own organisation

    Not all technical debt announces itself clearly. Some of the more reliable signals to watch for include:

    • Sprint velocity that keeps declining even as the team size stays constant or grows
    • An increasing ratio of bug-fix work to feature development across releases
    • Engineers consistently flagging “this will take longer than expected” without clear explanations
    • Onboarding time for new developers stretching beyond three months
    • Incident frequency trending upward without a corresponding increase in system complexity

    Any one of these in isolation might have another explanation. Several of them together, particularly if they are worsening quarter on quarter, is a reliable indicator that technical debt has become structurally significant.

    It is worth noting that technical debt is not always the result of careless engineering. Sometimes it is a product of rational decisions made under real constraints. A startup choosing to move fast during a critical funding round is making a legitimate trade-off. The problem arises when the debt never gets repaid, and when leadership does not even have visibility that the debt exists.

    What tech leaders can actually do about it

    Tackling technical debt requires both a cultural shift and a structural one. Here are the steps I have seen work consistently for engineering organisations in the UK.

    Make the debt visible

    You cannot manage what you cannot measure. Start by conducting a proper technical debt audit. This does not need to be an exhaustive six-month exercise; a focused two-week sprint where senior engineers map the highest-risk areas of the codebase can produce an immediately actionable picture. Tools like SonarQube, CodeClimate, and similar static analysis platforms give quantitative data to underpin what engineers already know qualitatively.

    Critically, this information needs to be communicated upward in business language, not engineering language. “We have significant coupling in our payment processing module” means nothing to a CFO. “Every new payment feature takes four times longer to ship than it should, costing us roughly £300,000 in delayed revenue annually” lands very differently.

    Allocate dedicated time, not just goodwill

    The most common failure mode for technical debt remediation is treating it as something engineers will do in their spare time. They will not, because there is no spare time. Sustainable teams ring-fence a genuine proportion of every sprint for debt work. The commonly cited figure is around 20 per cent of engineering capacity, though the right number depends heavily on the severity of your current position.

    Some organisations use a “debt budget” model, where technical debt work competes in the same prioritisation process as feature work, with explicit business cases attached. This approach has the advantage of making trade-offs transparent and forcing product leadership to engage with the real cost of ignoring infrastructure.

    Modernise incrementally, not catastrophically

    The classic mistake is the Big Rewrite: a decision to throw away the existing system and rebuild from scratch. This almost never ends well. The Strangler Fig pattern, where new functionality is built in a modern architecture alongside the legacy system and old components are retired gradually, is far more survivable. It preserves continuity, reduces risk, and allows the business to keep shipping whilst the underlying structure improves.

    For UK businesses operating in regulated sectors, particularly fintech and healthtech, incremental modernisation is often the only realistic option given compliance requirements. The UK government’s evolving guidance on software and AI regulation is adding further pressure on engineering governance, making architectural documentation and audit trails increasingly non-negotiable.

    Change how you talk about it at board level

    Technical debt is ultimately a financial and strategic issue, not just an engineering one. Boards that understand this invest accordingly. Boards that treat it as an internal IT concern tend to find out the hard way, usually when a competitor ships a feature in two weeks that takes their own team six months, or when a major incident causes a reputational and commercial hit that dwarfs the cost of the remediation they declined to fund.

    Getting board-level buy-in means translating engineering concerns into the language of risk management, competitive position, and long-term margin. It is the same discipline required when sourcing anything for the long-term health of a business, whether that is enterprise software contracts, supply chain agreements, or even sourcing reliable Universal 4×4 products for a field operations fleet. Good decisions require visibility of the true cost, not just the headline price.

    The long game: treating engineering health as a business metric

    The companies that handle technical debt well share a common trait: they treat engineering health as a first-class business metric, sitting alongside revenue growth, customer retention, and gross margin. They track it, report on it, and allocate resources to it with the same rigour they apply to commercial performance.

    That shift in framing is genuinely transformative. It changes the conversation from “why is engineering slow?” to “what is the return on investing in engineering quality?” And the answer, consistently, is that it is one of the highest-leverage investments a product-led business can make.

    Technical debt will always exist to some degree. The goal is not a perfectly clean codebase; that is an engineering fantasy. The goal is managed, visible, strategically acceptable debt, with a clear plan for repayment. Get that right, and the drag on growth becomes a competitive advantage waiting to be unlocked.

    Frequently Asked Questions

    What is technical debt in simple terms?

    Technical debt refers to the accumulated cost of shortcuts, quick fixes, and deferred maintenance in a software system. It is like financial debt in that it accrues interest over time: the longer it goes unaddressed, the more expensive and disruptive it becomes to fix.

    How do you measure the impact of technical debt on a business?

    Common indicators include declining sprint velocity, rising incident rates, increasing time-to-ship for new features, and growing onboarding time for new engineers. Tools like SonarQube or CodeClimate can provide quantitative code quality metrics, which can then be mapped to estimated engineering hours and revenue impact.

    How much engineering time should be spent on reducing technical debt?

    A widely recommended starting point is around 20 per cent of sprint capacity, though organisations with severe legacy issues may need to ring-fence more initially. The key is making this allocation explicit and consistent rather than relying on ad hoc cleanup.

    Can technical debt cause a business to fail?

    Directly, it is rarely a sole cause, but it can contribute significantly to competitive decline and operational risk. If a company cannot ship features at pace, retains poor engineering talent, and suffers increasing system outages, the commercial consequences can absolutely become existential over time.

    What is the difference between intentional and unintentional technical debt?

    Intentional technical debt is a conscious trade-off, for example shipping a working but imperfect solution to meet a launch deadline, with a plan to improve it later. Unintentional debt arises from inexperience, poor processes, or neglect. Both require management, but intentional debt is generally less damaging because it is visible and understood.