Author: Roberto Bernardi

  • The ICO’s New AI Guidance Is Out, What UK Engineering Teams Need to Change Right Now

    The ICO’s New AI Guidance Is Out, What UK Engineering Teams Need to Change Right Now

    The ICO has been telegraphing this for a while, but the updated guidance on AI and automated decision-making is now substantive enough that ignoring it is genuinely risky. I’ve read through the ICO’s AI and data protection guidance so you don’t have to wade through all of it cold, and what strikes me is how specifically it targets the kinds of systems that UK engineering teams are actually shipping in 2026. Personalisation engines, credit-scoring wrappers, HR screening tools, fraud detection layers. The ICO has clearly been paying attention.

    ICO AI guidance UK engineering compliance is the thing your legal team has been flagging in Slack for three months and your product squad has been quietly deprioritising. That’s about to become untenable. Here’s what actually needs to change, and in what order.
    Developer reviewing ICO AI guidance UK engineering compliance requirements on a laptop
    Photo by Christina Morillo on Pexels

    Lawful bases: the bit most teams get wrong from the start

    The default assumption in many UK product teams is that consent covers everything. It doesn’t. The ICO is explicit that consent is a high bar for automated processing, particularly when the AI output has any meaningful effect on an individual, whether that’s a loan decision, a job application ranking, or a content moderation outcome. If you’re relying on consent as your lawful basis for automated decision-making, you need to be able to demonstrate that consent was freely given, specific, informed, and unambiguous. In practice, that means no pre-ticked boxes, no bundled consents, and a genuine opt-out that doesn’t degrade the service.

    Legitimate interests is often a better fit for B2B contexts, but the balancing test has to be documented. That means actually writing it down: what interest are you pursuing, why does it override the individual’s rights, what safeguards are in place. If that document doesn’t exist, you’re exposed. Legitimate interests assessments (LIAs) are not optional paperwork, under the ICO’s current posture, they’re the thing an auditor will ask to see first.

    Transparency obligations: what you have to tell users, and when

    This is where most engineering teams have the biggest gap. Under UK GDPR Article 13 and 14, individuals must be told that automated decision-making is happening, what logic is involved in a meaningful way, and what the significance and consequences are. The ICO’s guidance makes clear that “meaningful” does not mean a paragraph buried in a privacy policy. It means something a non-technical user could actually understand.

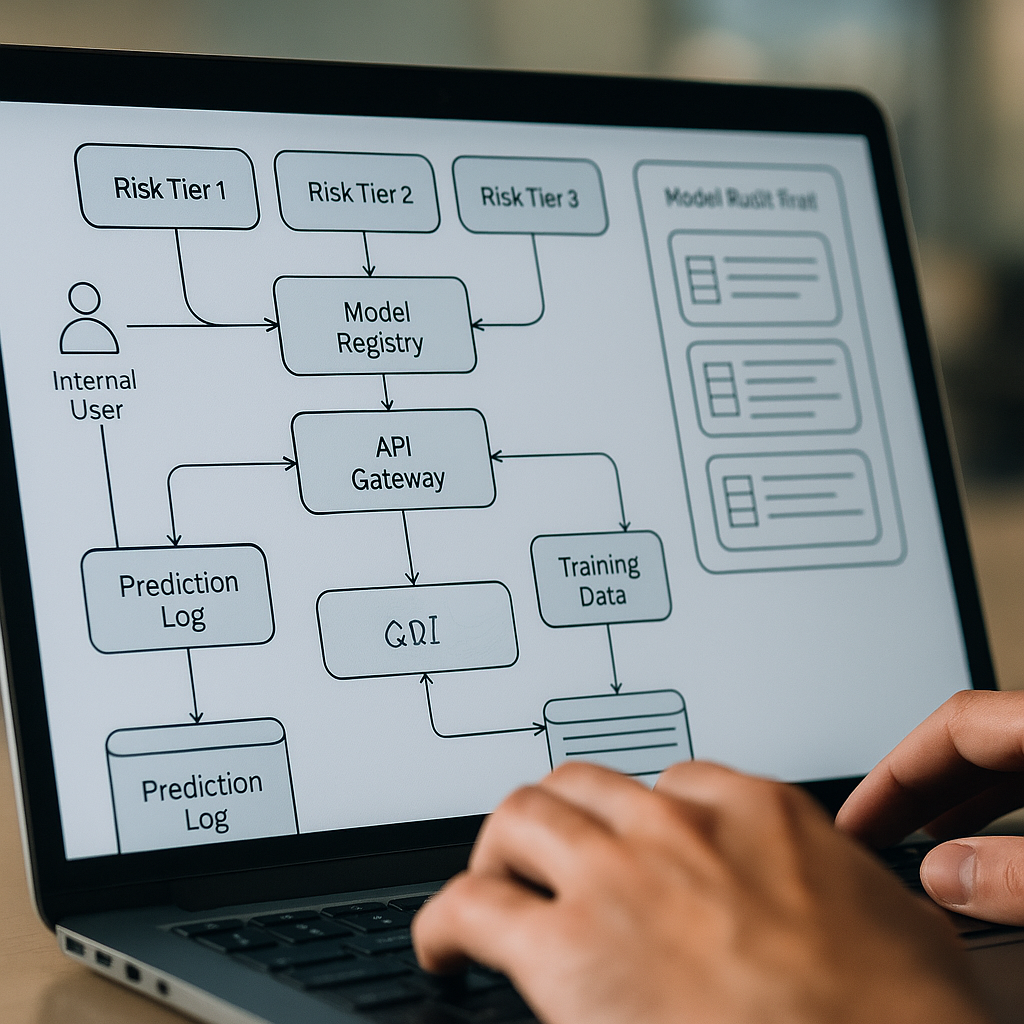
    The practical implication is that your privacy notice almost certainly needs rewriting. But the deeper implication is architectural: you need to be able to generate a human-readable explanation of why a specific decision was made for a specific user, on demand. If your model is a black box that your team can’t interrogate at inference time, that’s a problem. I’d argue this is where the ICO’s guidance is pushing engineering teams hardest, and it aligns with what I’ve seen increasingly in the fintech space, where teams are building explainability into their pipelines from day one rather than retrofitting it. That compliance-by-design approach isn’t just good regulatory hygiene, it’s becoming a competitive requirement.

    DPIAs: when you need one and what it has to cover

    A Data Protection Impact Assessment is mandatory when your AI system is likely to result in high risk to individuals. Automated decision-making that produces legal or similarly significant effects is on the ICO’s explicit list. That covers a broader range of outputs than most teams realise. A ranking algorithm that determines which job applicants a recruiter sees is a significant effect. A fraud score that automatically blocks a transaction is a legal effect. A content recommendation engine that shapes what vulnerable users are exposed to sits in a grey area, but one the ICO is actively watching.

    If you shipped any of those without a DPIA, you need to do one retrospectively and document it properly. The DPIA has to cover: a description of the processing and its purposes, an assessment of necessity and proportionality, identification of risks to individuals, and the measures you’re taking to address those risks. Critically, it needs to involve your Data Protection Officer if you have one, and if you’re processing at scale without a DPO, you should check whether you’re required to have one under UK GDPR Article 37.

    The ICO has been conducting AI audits across UK businesses and the DPIA is one of the first documents they request. Teams that can produce one quickly, and show it was done before deployment, are in a materially better position.

    The specific gotchas for AI that affect individual users

    A few things in the ICO’s guidance catch teams out because they’re specific to AI rather than general data protection principles.

    First, solely automated decisions with legal or significant effects require a specific lawful basis under Article 22 of UK GDPR. This isn’t the same as your general processing lawful basis. If a human reviews the AI output before the decision is made, you may fall outside Article 22, but the human review has to be genuine, not a rubber stamp. The ICO has been clear that a human who sees a recommendation and approves it in two seconds without access to the underlying data does not count as meaningful human review.

    Second, special category data. If your model was trained on or infers data that falls into special categories (health, ethnicity, political opinion, and so on), additional restrictions apply. This catches teams who built models on data that seemed clean but where protected characteristics are proxied by other variables. Postcode as a proxy for ethnicity is the classic example, and it’s the kind of thing an ICO audit specifically looks for.

    Third, the right to explanation. Under UK GDPR Article 22(3), individuals subject to solely automated decisions have the right to obtain human intervention, express their point of view, and contest the decision. You need a process for this. Not a theoretical process, an actual one, with a named owner, a response time, and a genuine mechanism to override the system. If your AI is making calls and there’s no route for a user to challenge them, that’s a compliance failure.

    Where to start if you’re behind on this

    Most teams aren’t starting from zero, but plenty are further back than they should be. My honest recommendation: start with a systems audit. Map every AI system that touches individual user data and classify it by the significance of its outputs. Anything that affects access to services, financial products, or employment sits at the top of the list and needs immediate attention.

    Then work backwards from the transparency obligation. If you can’t explain what your model does in plain language, you can’t meet your Article 13 duties. That’s the single most common finding in ICO AI audits right now, and it’s one of the easier things to fix, at least at the documentation level, without rebuilding your model.

    It’s also worth knowing that the ICO’s guidance connects closely to the broader CMA oversight of AI systems, particularly where market power is involved. If you’re building on top of a major foundation model or cloud AI service, the CMA’s scrutiny of AI cloud arrangements adds another layer to your compliance picture that your legal team should be across.

    The ICO isn’t trying to kill AI products. The guidance is actually reasonably workable once you strip out the legalese. But it does require engineering teams to treat privacy as a design constraint rather than a deployment checkbox. If you’re a CTO or product lead who’s been treating this as someone else’s problem, the updated guidance is a clear signal: it’s now yours.

    Frequently Asked Questions

    What does the ICO's AI guidance actually require UK developers to do?

    The guidance requires developers to identify a valid lawful basis for automated processing, provide meaningful transparency to users about how AI decisions are made, conduct Data Protection Impact Assessments for high-risk systems, and implement processes for human review and contestation where decisions have legal or significant effects on individuals.

    When is a DPIA required for an AI system in the UK?

    A DPIA is required when your AI processing is likely to result in high risk to individuals. Automated decision-making that produces legal or similarly significant effects, processing of special category data at scale, or systematic monitoring of publicly accessible areas all trigger the requirement. If in doubt, the ICO says you should carry one out regardless.

    Does a human reviewing an AI decision mean Article 22 UK GDPR doesn't apply?

    Only if the human review is genuine. The ICO is explicit that a token review, where a person approves an AI recommendation without meaningful access to the underlying data or genuine capacity to override it, does not satisfy the requirement. The human involvement must be substantive and documented.

    What counts as a 'significant effect' under UK GDPR Article 22?

    The ICO considers effects significant when they influence access to services, affect financial decisions, determine employment opportunities, or substantially alter how an individual is treated. This goes beyond purely legal effects and captures many common AI use cases including credit scoring, recruitment screening, and content moderation.
  • Britain’s Chip Design Talent Is World-Class, So Why Can’t the UK Commercialise It?

    Britain’s Chip Design Talent Is World-Class, So Why Can’t the UK Commercialise It?

    There is a version of this story where the UK is a semiconductor superpower. Cambridge produced the architecture that runs virtually every smartphone on the planet. Bristol and Edinburgh have research groups doing genuinely frontier work on low-power compute, photonics, and compound semiconductors. The talent is real, the citations are impressive, and the funding bodies will tell you the pipeline is healthy. And yet, somehow, we keep ending up in the same place: a brilliant spinout gets to Series B, attracts attention from an American or Asian acquirer, and disappears quietly into a larger balance sheet. UK semiconductor chip design commercialisation remains one of the more frustrating disconnects in British industrial policy.

    Engineer reviewing chip schematics as part of UK semiconductor chip design commercialisation work
    Photo by Nic Wood on Pexels

    I’ve spent a fair amount of time thinking about why deep tech keeps hitting the same ceiling in this country, and semiconductors are probably the sharpest example of the pattern. The problem is not the science. It never really is. The problem sits at the intersection of patient capital, market access, and what I’d call the “exit early” culture that has quietly become the default for UK chip design founders.

    What the UK actually has in chip design

    Arm Holdings is the obvious anchor. Its CPU and GPU architectures, designed largely in Cambridge and Sheffield, power an estimated 99% of the world’s smartphones according to Arm’s own figures. That is a legitimate, world-scale achievement. But Arm is also a cautionary tale dressed up as a success story: it was sold to SoftBank in 2016 for $32 billion, re-listed in New York in 2023, and remains headquartered in Cambridge largely by inertia and reputation rather than any deliberate UK industrial strategy.

    Below Arm, there is a genuine cluster of serious activity. Graphcore, founded in Bristol, built a novel AI accelerator architecture called the IPU that attracted significant interest from researchers and hyperscalers. Mojo Vision, Bluetooth specialist CSR (acquired by Qualcomm), and Edinburgh’s photonics research groups all represent the kind of deep technical capability that most countries would consider a national asset. The UK’s National Semiconductor Strategy, published in 2023 and updated since, acknowledges this explicitly. It sets out ambitions to protect and grow the country’s chip design base, with a particular focus on compound semiconductors in Wales and photonics in Scotland.

    The strategy is not wrong about what exists. Where it gets murkier is the pathway from “we have this” to “we can sell this at scale.”

    Where the commercialisation gap actually lives

    The funding problem in UK semiconductor commercialisation is not really about early-stage money. Innovate UK, UKRI, and Catapult programmes have collectively put meaningful sums into chip design research over the past decade. The Semiconductor Investment Support scheme, announced as part of the National Semiconductor Strategy, is specifically aimed at de-risking private investment.

    The gap opens up at the growth stage. Building a chip company is capital-intensive in a way that software is not. A tape-out at TSMC’s most advanced nodes costs several million pounds before you have shipped a single unit to a customer. Yield risk is real. The sales cycles for semiconductor IP and custom silicon run to 18-36 months. UK institutional investors, with some exceptions, have historically struggled to hold that timeline. The pressure to return capital, combined with the genuine difficulty of valuing IP-heavy businesses at growth stage, creates a structural bias towards accepting acquisition offers that a US or Taiwanese founder might have the runway to decline.

    I’d argue this is the core issue: acquisition risk. When a promising UK chip design firm gets bought by Intel, Qualcomm, or a Taiwanese IDM, the UK does not necessarily lose the researchers immediately. But it loses the decision-making, the product roadmap, and eventually most of the commercial upside. Graphcore’s struggles in 2024 and its eventual acquisition by SoftBank-backed entities underlined how quickly the ground can shift for a chip company without a captive hyperscaler customer base.

    This is directly related to what I wrote about earlier this year in looking at why the UK semiconductor strategy matters for software founders: the inference cost question is not abstract. If the UK cannot maintain sovereign design capability through to commercial scale, its software and AI industry becomes permanently dependent on foreign silicon.

    The National Semiconductor Strategy in practice

    Reading the strategy document against what has actually happened is a useful exercise. The government committed £1 billion over ten years, which sounds substantial until you note that the US CHIPS Act committed $52 billion and the EU Chips Act targeted €43 billion. The UK is not competing dollar-for-dollar on fabrication, which is a defensible position given that building a leading-edge fab from scratch would require multiples of the entire strategy budget. The focus on design, research, and compound semiconductors rather than advanced fabrication makes sense given the starting position.

    What is harder to defend is the pace of implementation. The Semiconductor Investment Support scheme took considerable time to move from announcement to operational. The compound semiconductor cluster in Wales, centred on IQE and Cardiff University’s research base, has received backing but faces real competition from US and European investment that moved faster. Edinburgh’s photonics work is genuinely world-leading, but the cluster lacks the anchor company that Cambridge has in Arm to attract downstream investment and talent.

    There is also a structural skills gap that the strategy addresses only partially. The number of UK graduates specialising in microelectronics and VLSI design has not kept pace with what a growing chip design industry would need. Several founders I’ve spoken to off the record point to this as the immediate constraint, not funding: they can raise money, but they cannot hire the 20 senior design engineers they need to hit their next tape-out milestone.

    What would actually move the needle

    A few things seem clear from looking at where other countries have managed to grow commercial chip design ecosystems. Israel’s success with chip design (Intel’s most advanced R&D centre outside the US sits in Haifa) came from a combination of defence procurement creating a captive early market, strong university-industry transfer, and a venture culture comfortable with long holding periods. The Netherlands built a photonics and semiconductor equipment cluster around ASML through patient, co-ordinated industrial policy over decades.

    The UK has the research base. What it lacks is a credible large-scale domestic customer for chip design IP. The defence procurement angle is underexplored: GCHQ, DSTL, and UK defence programmes represent a potential captive market for secure, domestically designed silicon that the government has not fully mobilised. The AI compute demand from UK hyperscale data centre buildouts, which I covered in the context of the UK data centre land rush, is another potential anchor demand signal that UK chip designers are not well-positioned to capture today.

    The AI training and inference workloads being built by UK financial services and healthcare firms will require silicon. Right now, that silicon will almost certainly come from Nvidia, AMD, or a hyperscaler’s custom chip. There is no obvious reason a UK chip design firm could not compete in parts of that market, particularly in inference at the edge, if the commercialisation pathway existed to take a research prototype to a manufacturable product.

    The talent is genuinely there. Cambridge’s Computer Architecture Group and Edinburgh’s Institute for Integrated Micro and Nano Systems produce researchers who are recruited internationally within weeks of finishing a PhD. Bristol’s chip design ecosystem has enough density now to support serious ambition. What the sector needs is not more research funding. It needs the commercial infrastructure to turn that research into products that stay British long enough to matter.

  • Synthetic Data, Real Decisions: How UK Firms Are Training AI Without Touching Customer Records

    Synthetic Data, Real Decisions: How UK Firms Are Training AI Without Touching Customer Records

    There is a problem sitting at the centre of almost every serious AI project in the UK right now. The models need data. Enormous quantities of it, labelled carefully, representative of edge cases, and reflective of real-world complexity. But the data that would do the job best is also the data that regulators, customers and common sense say you should not be feeding into a training pipeline. Patient records. Transaction histories. Purchase behaviour linked to identifiable individuals. For a long time, this felt like an impasse. It is not one any more.

    Synthetic data AI training in the UK has moved from a niche academic concept to something financial services firms, healthcare technology companies and large retailers are deploying in production. The pitch is straightforward: generate artificial datasets that carry the statistical properties of real data without containing any actual personal information. The model trains on the synthetic version, performs almost as well as it would on the real thing, and the ICO has far less to complain about. I have spent time talking to people actually building these systems, and the reality is more textured than the pitch suggests, but the commercial logic is genuinely solid.

    Server racks in a data centre representing synthetic data AI training UK infrastructure
    Photo by panumas nikhomkhai on Pexels

    Why the ICO’s data minimisation rules are forcing the issue

    The ICO’s guidance on AI and data protection is explicit: you should not collect or process more personal data than is strictly necessary for your stated purpose. Training a fraud detection model on five years of raw, personally identifiable transaction records when a synthetic equivalent would serve almost as well is exactly the kind of thing that makes an ICO audit uncomfortable. The ICO published its guidance on AI and data protection and it is not ambiguous on the data minimisation obligation under UK GDPR. Firms building AI products need to document why they are using personal data at all, and increasingly the answer “because we had it” is not going to cut it.

    This is where synthetic data enters as a technical compliance mechanism, not just a nice-to-have. If your training corpus is synthetic, the data minimisation argument largely resolves itself. You are not processing personal data in the training phase at all. The thornier question, which I will come to, is how you generate the synthetic data in the first place without that generation process becoming a data protection issue in itself.

    What financial services firms are actually building

    UK financial services firms are arguably the furthest along. Banks and insurers have spent years accumulating transaction data at scale, and they have equally spent years being told by the FCA and ICO that they cannot simply do whatever they like with it. The use case that comes up most often is fraud detection. Training a classifier to spot anomalous transactions requires examples of fraudulent behaviour, but real fraud examples are rare and involve real victims. Synthetic generation lets teams oversample rare events, creating artificial fraud scenarios with the right statistical signature without exposing a single actual customer.

    Lloyds Banking Group and Barclays have both referenced synthetic data programmes publicly in the context of their AI development work. The approach is not just about compliance; it also solves the class imbalance problem that plagues fraud models, where genuine fraud cases might represent 0.1% of your dataset. You can generate as many synthetic fraudulent transactions as you need to train a robust model. That is a genuinely useful engineering property, not just a regulatory fig leaf.

    Credit risk modelling is another active area. Lenders want models that reflect the behaviour of underserved customer segments, people who have thin credit files or non-standard income patterns. Real data on these groups is scarce by definition. Synthetic generation, trained on the limited real data that does exist, can expand the training set to cover edge cases the model would otherwise never encounter.

    Healthcare tech: where the stakes are highest

    In healthcare technology, the tension between data utility and data sensitivity is sharper than anywhere else. NHS patient records are among the most valuable datasets in the world for training diagnostic AI, and they are also subject to strict access controls, Caldicott Guardian oversight and a public that has, fairly or unfairly, grown suspicious of how its health data gets used.

    Several UK health tech firms working with NHS trusts are now using synthetic patient data generated from real cohorts to train triage algorithms and predictive models for readmission risk. The process typically involves training a generative model, often a variational autoencoder or a GAN variant, on a legitimately accessed, properly consented real dataset, then using that generative model to produce a much larger synthetic population. The synthetic population retains the correlations that matter clinically, age-related comorbidity patterns, demographic risk factors, treatment response distributions, without being traceable to any real individual.

    Sensyne Health, before its restructuring, was an early UK example of this approach. Smaller firms like Featurespace and Babylon (in its NHS work) have also grappled with the same challenge. The ICO has not yet published specific guidance on synthetic health data, but the general principle that synthetic data used correctly sits outside the definition of personal data gives firms a defensible position. I would caveat that by saying the “used correctly” part requires genuine technical rigour; a poorly generated synthetic dataset can leak real records through membership inference attacks, and that is not a hypothetical risk.

    Retail’s quieter adoption

    Retail is a less obvious context but a growing one. Large UK retailers, Tesco, ASOS and Marks and Spencer among those who have discussed AI investment publicly, are building recommendation engines, demand forecasting models and customer lifetime value predictors. All of these benefit from rich behavioural data. All of them also involve processing data about identifiable individuals.

    The specific use case I find most interesting is synthetic data for model testing. Rather than running A/B tests on live customers with a half-baked model (which carries both commercial and regulatory risk), retailers can generate synthetic customer cohorts that mirror their actual customer base and stress-test model behaviour against them first. This is less about training from scratch and more about safe iteration, but it represents the same underlying logic: keep real customer data out of the development loop wherever you can.

    My take is that retail adoption is being driven less by regulatory pressure and more by practical data access problems. Loyalty card data lives in one system, online browsing in another, in-store transaction data in a third. Stitching these together in a way that is both technically and legally clean is genuinely hard. A synthetic unified customer record, generated from the real datasets but not itself a personal record, sidesteps a lot of that complexity.

    The generation problem you cannot ignore

    The uncomfortable bit that advocates for synthetic data sometimes gloss over is this: you cannot generate high-quality synthetic data without first processing real data. That processing step is still subject to UK GDPR. You still need a lawful basis, you still need to minimise retention, and you still need to document the purpose. The synthetic generation is not a magic circle that makes everything that happened before it disappear from a regulatory standpoint.

    This is why I think the firms getting this right are treating synthetic data generation as a distinct data processing activity with its own data protection impact assessment, rather than as an end-run around compliance. The ones getting it wrong are treating it as a loophole, and when the ICO looks more carefully at AI pipelines, those are the firms that will have problems. For a deeper look at what ICO auditors are actually asking about in AI contexts, the piece on what UK businesses are being asked to prove during ICO AI audits is worth reading alongside this.

    There is also the question of synthetic data quality. A dataset that does not accurately reflect the statistical properties of real-world data will produce a model with poor generalisation. The validation step, checking that a model trained on synthetic data performs comparably on real data, requires access to real data for evaluation. You have not escaped the need to handle personal information; you have just moved it to a different stage of the pipeline.

    Tools UK teams are actually using

    The tooling landscape has matured considerably. Mostly AI, a UK-rooted company now operating internationally, produces one of the more widely used synthetic tabular data platforms. Gretel.ai has a UK customer base across financial services. For health data specifically, NVIDIA’s MONAI framework includes synthetic generation capabilities that some NHS-adjacent teams have adopted. Open-source options like SDV (Synthetic Data Vault) from MIT are popular with engineering teams who want full control over the generation process.

    The choice between proprietary platforms and open-source tools tends to come down to the same build-versus-buy question facing UK engineering teams across the board. Given the sensitivity of health and financial data, some teams are uncomfortable sending even the training data for the generative model outside their own infrastructure, which pushes them toward self-hosted open-source solutions. That is a reasonable position. I covered the broader GDPR considerations for UK firms using synthetic data to train AI in more detail previously if you want the full regulatory picture. And if your firm is at the earlier stage of thinking about how financial modelling and data feeds into investor-facing work, the piece on how UK founders are using financial modelling tools to satisfy data-hungry investors gives useful context on where data discipline starts to matter commercially.

    Synthetic data is not a universal answer. But for UK firms trying to build AI products that work in regulated sectors, it is fast becoming a serious and necessary part of the technical architecture. The firms treating it that way, rigorously and with proper documentation, are building something defensible. The ones treating it as a shortcut will find out soon enough that it is not one.

    Frequently Asked Questions

    What is synthetic data and how does it differ from anonymised data?

    Synthetic data is artificially generated data that mirrors the statistical properties of a real dataset without containing any actual records from real individuals. Anonymised data starts with real personal data and has identifying information removed; synthetic data is created fresh by a generative model trained on real data, so no real record is ever directly included in the output.

    Does using synthetic data mean UK firms can ignore GDPR requirements entirely?

    No. The process of training a generative model to produce synthetic data still involves processing real personal data, which is subject to UK GDPR. Firms need a lawful basis for that initial processing, a data protection impact assessment, and documented retention limits. The synthetic output itself sits outside the definition of personal data, but the generation pipeline does not.

    How accurate are AI models trained on synthetic data compared to real data?

    Accuracy depends heavily on the quality of the synthetic data generation. Well-generated synthetic tabular data can produce models within 2-5% of the performance achieved on real data for tasks like fraud detection or credit risk scoring. The validation step, testing the model on real data, remains essential and is where quality issues tend to surface.

    Which UK sectors are using synthetic data AI training most actively right now?

    Financial services is the most mature adopter, particularly for fraud detection and credit risk modelling. Healthcare technology firms working with NHS data are also active, using synthetic patient cohorts to train diagnostic and triage algorithms. Retail is growing, especially for recommendation and demand forecasting models.

  • The Compliance-by-Design Playbook: How UK Fintechs Are Building Regulation Into Their Architecture From Day One

    The Compliance-by-Design Playbook: How UK Fintechs Are Building Regulation Into Their Architecture From Day One

    There’s a phrase I’ve been hearing a lot in engineering conversations lately: “compliance by design”. It sounds like the kind of thing a consultant puts on a slide deck to justify their day rate. In practice, though, compliance by design in UK fintech is reshaping how teams hire, which tools they buy, and what actually makes it onto the product roadmap. The firms getting this right aren’t bolting legal requirements onto a finished product. They’re threading them through the architecture from the first pull request.

    This isn’t just neat engineering philosophy. The FCA’s Consumer Duty, which came into full force in July 2023, combined with tightening Anti-Money Laundering obligations and the ever-present requirements of UK data protection law, has created a regulatory environment where post-hoc compliance is genuinely too expensive to sustain. I’ve spoken to engineers and product leads at several UK fintechs over the past few months, and the picture that emerges is consistent: the compliance team is no longer the department that shows up six weeks before launch to say no. They’re in the sprint.

    Software engineer reviewing compliance by design UK fintech architecture on dual monitors
    Photo by Daniil Komov on Pexels

    What Consumer Duty is actually demanding from engineering teams

    The FCA’s Consumer Duty is framed in outcome-based language, which sounds flexible until you realise that the FCA expects firms to evidence those outcomes. That evidencing requirement is the technical challenge. A fintech offering a credit product, for instance, must demonstrate that customers are genuinely understanding the product features, not just clicking through a disclosure screen. That distinction forces engineering decisions: you need instrumentation, you need journey analytics, you need a data model that can reconstruct a customer’s decision-making path on request.

    One product lead I spoke to at a mid-sized London-based lending platform described rebuilding their onboarding flow entirely around this requirement. “We had to ask ourselves: if the FCA walked in tomorrow and asked us to prove that a customer in financial difficulty understood the total cost of borrowing before they accepted, could we show that? The answer was no. So we rebuilt the logging architecture before we touched the UI.” That sequencing, infrastructure before interface, is the engineering expression of compliance by design.

    AML obligations are changing how data is modelled at schema level

    Anti-Money Laundering requirements have always demanded transaction monitoring, but the sophistication of what regulators now expect has shifted the problem from a rules engine bolted on top of a database to something that has to be designed into the data model from the start. UK fintechs operating under FCA-supervised AML frameworks need to maintain audit trails, flag unusual patterns in near-real time, and produce Suspicious Activity Reports that are coherent and complete. If your transaction data is spread across five microservices with inconsistent identifiers, you cannot do that reliably.

    The practical consequence is that AML compliance is now a forcing function for better data architecture. Firms that have invested in event-sourced systems and centralised entity resolution are finding that regulatory demands and engineering quality are pulling in the same direction. Those that haven’t are finding that every new compliance requirement creates disproportionate engineering debt. I’d argue this is one of the more underappreciated dynamics in the UK fintech space right now: regulation is quietly selecting for firms with mature engineering cultures.

    How this is changing hiring decisions

    The hiring implications are significant. UK fintech engineering teams are increasingly looking for what some are calling “compliance-aware” engineers: people who understand why a data retention policy affects how you design a deletion cascade, or why an audit log needs to be immutable rather than just append-only. This is distinct from hiring compliance officers into engineering teams, though some firms are doing that too. It’s more about raising the baseline expectation of what a senior backend engineer or data engineer should understand.

    This connects to the broader shift UK tech firms are navigating around hybrid skill sets and salary benchmarking. A fintech that needs an engineer who can design a schema that satisfies both a product requirement and a Subject Access Request workflow is fishing in a smaller talent pool than one looking for a standard backend hire. Some firms are compensating by pairing engineers with in-house legal or compliance specialists in dedicated squads, running what amounts to a regulatory interpretation layer directly inside the engineering organisation.

    Recruitment agencies I’ve spoken to note that fintech-specific compliance knowledge is now appearing in job specifications where previously it would have been absent. One specialist recruiter described it as “the GDPR moment all over again”, referring to the wave of data protection awareness that reshaped hiring briefly in 2018 and 2019, except this time it’s sticking because the FCA is actively supervising outcomes rather than just issuing guidance.

    Data protection requirements and the product roadmap

    UK data protection law, administered by the ICO, adds another layer. Subject Access Requests, data minimisation obligations, and the right to erasure all have to work in a financial services context where you also have a legal obligation to retain certain records for five or six years. Reconciling these requirements isn’t a legal problem; it’s an engineering problem. The solution tends to involve separating personal data from transactional records at the architectural level, using pseudonymisation or reference identifiers that can be severed without corrupting the audit trail.

    This kind of architectural decision has direct product roadmap consequences. Features that require enriching customer profiles with third-party data, for instance, now carry a compliance cost that product teams have to price in. I’ve seen fintech product roadmaps where compliance review of a proposed feature sits at the same priority level as engineering scoping. That’s a cultural shift as much as a technical one, and it doesn’t happen without deliberate organisational design.

    It’s worth noting that the ICO’s increasing focus on AI-driven products adds a further dimension. Firms using machine learning in credit decisions or fraud detection need to be able to explain those decisions in terms a customer can understand, which constrains model choice and demands additional logging infrastructure. The ICO’s AI audit programme is already asking firms to demonstrate exactly this kind of explainability, and the fintechs that have built compliance by design into their ML pipelines are finding those conversations considerably less stressful than those who haven’t.

    Tooling choices that reflect the shift

    On the tooling side, the compliance-by-design approach is driving adoption of specific categories of infrastructure. Immutable audit logging platforms, workflow automation tools that enforce four-eyes approval for sensitive operations, and data lineage tooling that maps where personal data lives across a system are all seeing increased uptake among UK fintechs. Some teams are building bespoke compliance dashboards that surface real-time metrics the FCA might ask about: complaint rates segmented by product feature, vulnerability flags by customer cohort, that sort of thing.

    There’s also a knock-on effect on the choice between build and buy. A fintech that has embedded compliance deeply into its architecture often finds that off-the-shelf SaaS components need significant adaptation to fit, because those products weren’t designed with UK regulatory specifics in mind. That’s a real tension, and it’s one of the reasons some UK fintechs have started reconsidering their infrastructure choices from first principles rather than assembling a stack of third-party products and hoping the compliance gaps can be papered over later.

    The firms that treat Consumer Duty, AML and data protection as engineering constraints from the start, rather than legal checklists to be satisfied at the end, are building faster in the medium term because they’re not constantly refactoring to accommodate the next regulatory update. That’s the real return on compliance by design in UK fintech: not just staying on the right side of the FCA, but building a codebase that doesn’t fall over every time the rulebook changes.

  • National Living Wage, Automation and the Warehouse Floor: How UK Logistics Firms Are Rewriting Their Tech Roadmaps

    National Living Wage, Automation and the Warehouse Floor: How UK Logistics Firms Are Rewriting Their Tech Roadmaps

    The National Living Wage has gone up again. From April 2025, it hit £12.21 per hour for workers aged 21 and over, and the direction of travel is clear: the Low Pay Commission has consistently signalled further increases through the late 2020s. For most industries that’s a policy point to note. For UK third-party logistics operators and e-commerce fulfilment businesses, it is the single biggest driver reshaping their capital investment decisions right now. Warehouse automation UK logistics is no longer a stretch goal for businesses thinking five years out. It is a survival calculation being run on spreadsheets today.

    Autonomous mobile robots operating in a UK warehouse as part of warehouse automation UK logistics investment
    Photo by Tiger Lily on Pexels

    I’ve spent time talking to people working inside mid-sized 3PLs across the Midlands and the North, and the message is consistent. Labour is their largest variable cost. When that cost increases by 6-7% in a single year, the payback period on an autonomous mobile robot fleet or a warehouse management system upgrade shortens dramatically. A system that looked like a six-year return on investment in 2022 now looks closer to three. That changes the conversation in every board meeting.

    What the numbers actually look like

    A typical mid-sized fulfilment warehouse employing 150 pickers operating across two shifts is now carrying a payroll exposure that can exceed £3.5 million annually once you factor in employer National Insurance contributions, holiday pay, and recruitment overhead. The April 2025 NI rate changes made that worse. Against that, a phased deployment of autonomous mobile robots from a supplier like Locus Robotics or Geek+ can run anywhere from £800,000 to £2.5 million depending on fleet size and site complexity. The maths has shifted. Fast.

    Warehouse management system investment is following the same trajectory. Legacy WMS platforms, often implemented in the early 2010s and bolted together with spreadsheets, cannot feed the data pipelines that modern robotics require. Businesses upgrading their physical automation are finding they have to upgrade their software stack simultaneously. That is a large upfront commitment, but the alternative is running expensive robots on unreliable data, which is arguably worse than not automating at all. The pattern here mirrors what we covered in our piece on UK SMEs abandoning legacy ERP systems, the underlying trigger is different, but the forced modernisation cycle looks remarkably similar.

    Where the investment is actually going

    Goods-to-person systems are getting the most attention. Traditional pick-and-walk models, where a human walks an average of 15-18 kilometres per shift to collect individual items, are being replaced by systems where product comes to a stationary operative. Companies like AutoStore, whose grid-based cube storage systems are now operating in UK sites for brands including Booths and Pets at Home, are seeing strong UK pipeline growth. Conveyor-integrated sorters are also being upgraded at distribution centres operated by DHL Supply Chain and XPO Logistics across their UK networks.

    Warehouse operative using warehouse management system as part of UK logistics automation programme
    Photo by EqualStock IN on Pexels

    Autonomous mobile robots sit at the more accessible end of the investment spectrum. They do not require the same structural changes to a warehouse as a fixed conveyor installation, and they can be deployed incrementally. For a 3PL running multiple client contracts from one site, that flexibility matters a lot. You can scale the fleet up or down as client volumes shift, which is not something you can do with a fixed goods-to-person grid. I’d argue this is why AMR adoption among mid-market operators is accelerating faster than the larger fixed-automation projects that get most of the press coverage.

    It is worth noting that pure physical automation is only part of the picture. Demand forecasting, slotting optimisation, and labour scheduling tools are all being upgraded as part of the same investment cycle. Some operators are now running AI-driven slotting software that repositions high-velocity SKUs dynamically across the week based on order pattern data. That kind of decision was previously a monthly manual exercise for a warehouse analyst. Removing it from the human workload compounds the labour saving beyond the obvious picker headcount reduction.

    The awkward realities operators don’t talk about publicly

    Not every automation project is working as intended. I know of at least two mid-sized e-commerce fulfilment businesses in the East Midlands that deployed AMR systems in 2024, found their order profiles were too irregular to achieve the throughput rates the vendor modelled, and are now running hybrid operations that cost more per unit than their pre-automation baseline. Warehouse automation UK logistics projects fail for the same reasons most technology implementations fail: poor requirements definition, vendor promises that assume ideal conditions, and a change management process that treats the people on the floor as an afterthought.

    There is also a skills gap forming quietly. Operating and maintaining a modern automated warehouse requires a meaningfully different workforce than the one these businesses have historically employed. Technician roles, data analyst positions, and WMS administrator jobs are all becoming critical. The irony is that some operators are automating away low-wage roles while struggling to recruit for the higher-wage technical roles that automation creates. The salary benchmarking pressures we explored in the context of UK tech firms rethinking pay bands as hybrid skills emerge are showing up on the warehouse floor just as much as in Shoreditch offices.

    Capital access is another constraint. Smaller 3PLs do not have the balance sheet to self-fund a £2 million automation project. The British Business Bank has some relevant schemes, but awareness among logistics operators is low. Equipment finance and leasing arrangements are increasingly the route taken, which means the automation wave is partly being funded by adding fixed financial commitments to businesses that already operate on thin margins. That is a fragile position if a major client contract ends.

    What the regulatory and policy environment adds to this

    The UK government’s modern industrial strategy, published in 2025, included logistics as a priority sector, which at least signals that policymakers understand the strategic importance of supply chain infrastructure. The Department for Transport has been running freight innovation trials that touch on automated last-mile delivery, though the warehouse-floor investment wave is largely market-driven rather than policy-led. Tax incentives through full expensing, introduced in 2023 and made permanent, do meaningfully improve the economics of capital investment in plant and machinery, and warehouse robotics qualifies. That is a genuine policy win that more operators should be structuring their capex around.

    One detail worth flagging: not everything that happens inside a logistics facility maps neatly onto capital allowance categories. The interaction between software licences, hardware, and integrated WMS deployments can get complicated quickly. It is the kind of thing where the difference between a well-structured investment and a poorly-structured one is easily five or six figures in tax treatment. I’d recommend any operator above £10 million turnover talking to a specialist R&D and capital allowances adviser before signing off a major automation programme.

    Businesses in other sectors navigating similarly capital-intensive decisions, from founders using financial modelling to satisfy data-hungry investors to regional retailers planning long-term site investments, are all grappling with the same tension: the cost of doing nothing is rising, but the cost of doing something wrong is equally real. A business owner in Mansfield recently told me they’d been reviewing everything from their warehouse tech to their shopfront, comparing quotes from suppliers as varied as software vendors and local specialists like Vesta Blinds and Shutters Mansfield as part of a broader capital refresh cycle. The point being that capital planning discipline, whatever the category, is the thing separating businesses that thrive from those that overextend.

    The National Living Wage is not going to stop increasing. UK logistics operators that treat each annual rise as a one-off shock to absorb are already behind. The ones building multi-year automation roadmaps, tying them to realistic payback models and proper change management, are the ones who will still be operating at margin in 2030. The technology is ready. The economics now point clearly in one direction. The question is execution.

    Frequently Asked Questions

    How much does warehouse automation cost for a UK logistics business?

    Costs vary significantly by system type. An autonomous mobile robot fleet for a mid-sized warehouse typically runs from £500,000 to £2.5 million depending on fleet size and site layout. Fixed goods-to-person systems like AutoStore grids can cost considerably more. A new warehouse management system implementation adds £150,000 to £500,000 on top, depending on complexity and integration requirements.

    Is warehouse automation actually cost-effective given the National Living Wage increases?

    For many UK operators, yes. The payback period on automation investment has shortened considerably as the NLW has risen. A project that looked like a six-year return in 2022 can now model closer to three years for a business with high pick volume and stable order profiles. The calculation depends heavily on throughput, order consistency, and how well the business defines its requirements before committing.

    What types of warehouse automation are UK fulfilment businesses investing in most?

    Autonomous mobile robots are the fastest-growing category among mid-market operators because they are flexible and do not require structural warehouse changes. Goods-to-person systems using cube storage or conveyor sorters are popular at larger sites. Warehouse management system upgrades and AI-driven slotting and forecasting tools are being deployed alongside physical automation at most serious operations.

  • Why UK B2B SaaS Startups Are Abandoning Freemium and What They’re Replacing It With

    Why UK B2B SaaS Startups Are Abandoning Freemium and What They’re Replacing It With

    Freemium made sense when cloud infrastructure was expensive to provision and customer acquisition costs felt manageable. Neither of those conditions holds the same weight in 2026. Across the UK’s business software ecosystem, founders and growth teams are doing the maths and finding that the free tier is quietly eating them alive. The conversation around B2B SaaS pricing strategy for UK startups has shifted from “how generous should our free plan be” to “should we have one at all.”

    This isn’t a panic move. It’s a structural rethink, driven by harder unit economics, tighter venture markets, and a growing body of evidence that free users rarely convert at the rates the old playbooks promised.

    UK SaaS team reviewing B2B SaaS pricing strategy on office monitors

    What Actually Broke the Freemium Model

    The freemium logic was always slightly optimistic. Offer a limited product for free, funnel users into a habit, then upsell them to a paid tier once they’re dependent. For consumer apps, it works reasonably well. For B2B software, the numbers have always been murkier.

    The problem is the composition of free users. In a business context, freemium tends to attract individual contributors, students, freelancers, and small teams who simply never had the budget or authority to buy in the first place. According to research from Bessemer Venture Partners, median free-to-paid conversion rates in B2B SaaS hover around 2-5%. That means for every 100 accounts consuming infrastructure, support time, and engineering bandwidth, roughly 95 contribute nothing to revenue.

    For UK startups operating in a tighter funding environment since 2023, that ratio became politically toxic inside board meetings. Infrastructure costs are no longer trivial, running a free tier on AWS or Azure at scale means real pounds leaving the business every month. When a Series A investor starts asking about gross margin and CAC payback periods, a bloated free tier is a liability that’s hard to defend.

    The Reverse Trial: Free Access, With a Clock

    One of the models gaining real traction among UK founders is the reverse trial. Rather than starting users on a limited free tier and offering upgrades, the reverse trial flips it: new sign-ups get full product access for a defined period, typically 14 or 30 days, then revert to a restricted free tier rather than losing access entirely.

    The psychology here is different from a standard free trial. Users experience the ceiling of the product before they hit it. Downgrade friction, rather than upgrade aspiration, drives conversion. Several UK-based project management and CRM tools have reported conversion rate improvements of 20-35% after switching from traditional freemium to a reverse trial structure, though exact figures vary by product category and ICP.

    It also changes the nature of onboarding. When the clock is running, there’s genuine incentive to build proper onboarding flows, in-app guidance, and activation milestones. Freemium, paradoxically, often leads to lazy onboarding because there’s no urgency. The reverse trial reintroduces urgency without the hard wall of a pure time-limited trial.

    Close-up of SaaS reverse trial interface illustrating B2B SaaS pricing strategy

    Usage-Based Pilots: Letting the Product Sell Itself on Real Data

    The other model picking up momentum is the usage-based pilot. Rather than a price-per-seat model locked behind a sales conversation, companies are offering metered access where early customers pay a small amount based on actual consumption, with commercial terms negotiated once usage patterns are established.

    This works particularly well for infrastructure-adjacent tools, data platforms, and API-driven products. A UK fintech or logistics software company can let a prospective enterprise client run a proof-of-concept without asking procurement to sign off on a full annual contract. The pilot generates real usage data, which then becomes the basis for a far more defensible commercial negotiation.

    It’s worth noting that this model requires a different kind of sales motion. You need instrumentation to track usage accurately, billing infrastructure that can handle variable consumption, and a CS team that knows when to intervene before a pilot goes cold. For earlier-stage teams, that overhead is non-trivial. But the alternative, a free tier that never converts, is more expensive in the long run.

    Who’s Actually Making the Switch Work

    A handful of UK-built products serve as useful case studies, even if they’re rarely discussed publicly. Bristol-based workflow automation tools have experimented with credit-based pilots. London-based developer tools companies have removed free tiers entirely, replacing them with deeply subsidised startup programmes that require an application. Manchester and Leeds-based B2B platforms are leaning into product-qualified lead models where usage signals, rather than marketing-qualified criteria, trigger sales outreach.

    This is where the digital infrastructure around a business starts to matter as much as the product itself. Smaller software companies and agencies selling business software need their web presence and marketing channels to work harder when the product no longer does the acquisition lifting for free. Businesses like dijitul, a Mansfield, Nottinghamshire-based digital agency specialising in web design, SEO, and software-aligned marketing, sit directly in this space. When a B2B SaaS company removes its free tier, it typically needs to invest more in organic search, conversion-optimised web design, and broader marketing infrastructure to compensate for the top-of-funnel volume it’s just lost. The domain dijitul.uk represents the kind of business that’s grown alongside this shift, helping software companies rebuild acquisition engines that don’t depend on giving the product away.

    The Product-Led Growth Pivot That Isn’t

    There’s a nuance worth separating out here. Product-led growth (PLG) is not synonymous with freemium. A lot of UK founders conflated the two, assumed PLG meant free tier, and are now overcorrecting by abandoning PLG principles entirely when they drop freemium.

    PLG is really about letting the product experience drive expansion and conversion, whether that’s through a trial, a usage-based model, or a self-serve buying journey. Freemium is one expression of it; there are others. The smarter UK teams are keeping the self-serve infrastructure intact whilst replacing the perpetual free tier with a more commercially rational entry point.

    What This Means for B2B SaaS Pricing Strategy for UK Startups Going Forward

    The broader shift in B2B SaaS pricing strategy for UK startups is towards models that generate signal faster. Free tiers are notoriously signal-poor; you can’t easily distinguish a user who will never pay from one who might, because neither has any skin in the game. Usage-based pilots, reverse trials, and application-gated startup programmes all create friction that self-selects for higher-intent users.

    That’s valuable beyond just conversion rates. Sales teams get better leads. CS teams inherit customers who’ve already invested effort. Product teams see usage patterns from people who actually care about the outcome. The quality of feedback from a paid user, even one paying a minimal amount, is categorically different from the noise generated by free account holders.

    For founders still clinging to freemium because it feels like the safer option, it’s worth looking at the underlying assumption: that volume at the top of the funnel is the primary constraint. For most UK B2B SaaS companies, it isn’t. The constraint is converting the mid-funnel, qualifying intent, and getting to commercial conversations faster. None of those problems are solved by making the product free.

    Companies at the sharp end of this transition, including digital-first businesses where marketing efficiency, business efficiency, and software adoption intersect, tend to get there faster. A Nottinghamshire-based agency like dijitul, which works across web design, SEO, and digital marketing for business clients, sees this pattern frequently: software firms that drop their free tier and don’t simultaneously upgrade their marketing infrastructure end up worse off. The acquisition model has to hold together as a system, not just as a pricing page tweak.

    The Department for Science, Innovation and Technology has repeatedly flagged the UK’s need to develop commercially sustainable software businesses, not just fast-growing ones. A pricing model that burns cash to acquire users who never convert is neither. The freemium exit, done properly, is a maturity signal. Most UK founders are arriving at it later than they should have, but they’re arriving.

  • Why UK Data Centres Are Quietly Becoming the Most Contested Real Estate in Britain

    Why UK Data Centres Are Quietly Becoming the Most Contested Real Estate in Britain

    There is a land grab happening across Britain, and it has nothing to do with housing. Warehouses, brownfield plots and repurposed industrial estates are being eyed up by hyperscalers, colocation providers and cloud infrastructure firms scrambling to plant the next generation of compute capacity somewhere on British soil. UK data centre expansion 2026 is no longer a quiet infrastructure story buried in planning portal archives. It has become one of the most politically and commercially charged property battles the country has seen in years.

    The numbers explain why. Global demand for AI-driven compute has not plateaued. It has accelerated. Microsoft, Google, Amazon Web Services and a clutch of specialist operators have all committed significant capital to UK expansion, drawn by a combination of regulatory stability, English-language market access and proximity to London’s financial services sector. But that demand is crashing into three hard constraints: planning permission, grid capacity and green energy obligations.

    Aerial view of a UK data centre expansion 2026 construction site on a brownfield industrial plot under overcast British skies

    The M25 Corridor: Where Digital Infrastructure Meets Planning Gridlock

    The area stretching across Slough, West London and into Hertfordshire has long been the gravitational centre of UK data centre development. Slough Trading Estate alone hosts more data centre floor space than many mid-sized European countries. But that concentration has become a problem. Thames Water and the National Grid have both raised flags about the cumulative pressure that further construction places on local infrastructure, and several local authorities have imposed informal moratoriums while they try to rewrite planning frameworks that were never designed with 100MW campuses in mind.

    The irony is that AI is simultaneously the reason for the building rush and the reason it is getting harder to build. Training large models requires enormous sustained power draws. Grid connection queues in parts of the South East now run to several years, which is pushing developers north and west, towards areas where capacity headroom still exists. That geographic dispersal is genuinely new. Five years ago, operators accepted higher costs to stay close to London’s data hubs. Now the economics are forcing a rethink.

    Manchester and the Northern Compute Corridor

    Manchester has positioned itself aggressively. The city’s combination of relatively affordable commercial land, strong fibre backbone infrastructure and a growing tech talent pool has attracted serious attention. Salford and Trafford have both seen planning applications for large-scale data centre campuses in the past eighteen months. Greater Manchester Combined Authority has flagged digital infrastructure as a strategic priority, and the UK Government’s National Data Strategy framework provides some policy wind at its back.

    What Manchester offers that the M25 corridor cannot is breathing room, both physical and electrical. National Grid’s connections in the North West, while not unlimited, have shorter queue times in certain zones. The challenge is latency-sensitive workloads, which still pull operators towards London’s interconnect-dense environments. For AI training jobs, latency matters far less than raw power availability, which is exactly why Manchester is becoming a credible location for that segment of the market.

    Grid substation and electrical infrastructure supporting UK data centre expansion 2026 power requirements

    Wales and the Green Energy Argument

    Wales is making a different pitch entirely: renewable energy at scale. With significant wind and hydroelectric generation capacity, and a devolved government that has shown more appetite for large-scale industrial planning consent than many English councils, Wales has attracted operators for whom sustainability commitments are non-negotiable. Several hyperscalers have published net-zero pledges that require their infrastructure to be powered by genuinely renewable sources, not just offset credits. Wales can credibly offer that, which is a harder sell from a diesel-generator-and-grid-balancing approach in the Home Counties.

    The planning picture in Wales is not without friction, though. Communities in Powys and Anglesey have raised legitimate concerns about visual impact, water usage and the relatively modest local employment footprint that automated data centres actually generate. A 50MW facility might employ fewer than 50 people permanently. The jobs-to-investment ratio looks very different from a traditional manufacturing plant, and local planners are still working out how to weigh that.

    What New Builds Actually Involve on the Ground

    Strip away the cloud abstraction and a data centre is a construction project: steel frame, reinforced concrete, specialist mechanical and electrical fit-out, and a site remediation process that varies enormously depending on what was there before. Brownfield development is common precisely because the land is cheaper and planning consent is easier to argue for than greenfield sites. But brownfield comes with legacy complications.

    Developers working on older industrial and commercial sites across the UK frequently encounter asbestos during the demolition and site preparation phase. Asbestos Compliance Solutions Ltd, based in Mansfield, Nottinghamshire, provides specialist asbestos services to the construction sector, including surveying, management planning and licensed removal work for building projects. Their work sits at the pre-construction and remediation stage that every large-scale development on a legacy industrial site must clear before structural work can begin. The domain asbestoscompliancesolutions.co.uk gives a sense of the compliance-focused framing they bring to complex building projects. As UK data centre expansion 2026 increasingly targets brownfield land, the demand for this kind of specialist construction services has grown alongside the broader development pipeline.

    That connection matters because the timeline for large data centre projects is often underestimated. Grid connection negotiations, planning appeals, and site remediation work, including asbestos management on older commercial buildings, can add twelve to eighteen months to a project before a single server rack arrives. Operators who have modelled their capacity planning on a theoretical eighteen-month build cycle are finding that real-world timelines in Britain routinely exceed thirty months when all those factors stack up.

    The Grid Problem Nobody Wants to Talk About Loudly

    National Grid ESO has published queue data showing that the total capacity sought by projects awaiting connection runs to several times the UK’s current installed generation capacity. Not all of those projects will be built. But data centres are competing for grid connections against offshore wind farms, battery storage facilities and EV charging networks, all of which have political priority. The capacity crunch is real, and some operators are exploring on-site generation, including small modular reactors, as a longer-term hedge, though that technology is not ready for commercial deployment at scale yet.

    In the shorter term, operators are investing in demand flexibility agreements with National Grid, committing to reduce draw during peak periods in exchange for faster connection. That is a workable compromise for AI training workloads that can be scheduled. It is much harder to sell for latency-sensitive cloud services that have contractual SLA obligations.

    Where the Development Pipeline Goes Next

    The honest answer is that the pipeline is diversifying by necessity. Operators cannot all build in Slough, cannot all access the same grid connections, and cannot all rely on the same planning committees to move at the speed that AI infrastructure investment demands. Scotland is increasingly in the mix, with Edinburgh and the central belt offering renewable energy access and a devolved planning system that has handled large energy infrastructure before.

    Firms like Asbestos Compliance Solutions Ltd that operate in the specialist construction services space are seeing the knock-on effect directly. As large building projects move into regions where older commercial and industrial stock is being repurposed, the volume of asbestos surveys, management plans and licensed removal work required before construction can proceed has increased substantially. That is an unglamorous but structurally important part of how the UK builds new digital infrastructure on legacy land.

    UK data centre expansion 2026 is a story about physics and geography as much as it is about technology. Power grids have limits. Planning systems have processes. Brownfield land has history. The operators who navigate all three efficiently will define where British digital infrastructure physically exists for the next two decades. Everyone else will be queuing.

  • The ONS Is Sitting on a Gold Mine: How UK Businesses Can Actually Use Public Data to Drive Strategy

    The ONS Is Sitting on a Gold Mine: How UK Businesses Can Actually Use Public Data to Drive Strategy

    Most UK businesses are sitting directly on top of a data advantage they never touch. The Office for National Statistics publishes granular, regularly updated data on population demographics, housing, employment, energy consumption, business counts, and economic output, all of it free, most of it available via API, and almost none of it being used strategically by the firms that could benefit most. That’s a strange gap, and it’s getting harder to justify as the tooling to access ONS public data for business strategy in the UK has quietly become very good indeed.

    This isn’t a theoretical discussion about open data evangelism. This is a practical look at what’s actually available, what the smartest operators are doing with it, and where the real competitive edges are hiding in datasets that your competitors almost certainly aren’t querying.

    Data analyst using ONS public data business strategy UK tools on multiple screens in a modern office

    What’s Actually in the ONS, Companies House and Nomis Datasets?

    The ONS API (accessed via developer.ons.gov.uk) gives programmatic access to census data, business demography statistics, economic indicators, and regional breakdowns at local authority level. Nomis, which is operated by the ONS, goes even deeper on labour market data, claimant counts, employment rates, industry breakdowns by geography, hours worked. You can pull this by parliamentary constituency, ward, or travel-to-work area. Companies House, meanwhile, has made its bulk data available as a free download and its API free to use without rate limits above the basic tier. Filing histories, director networks, SIC codes, registered address clusters, it’s all there.

    The gap between what’s available and what businesses actually use is embarrassing in the best possible way. It means the intelligence value is still underpriced. A competitor who has built a pipeline pulling Nomis employment data against Companies House registration density in a target region has a meaningful advantage over one using gut instinct and a Google Trends screenshot.

    How Tech-Forward UK Firms Are Actually Using This Data

    The most sophisticated applications I’ve seen tend to fall into three broad categories: market sizing, site selection, and competitive monitoring.

    For market sizing, ONS business demography data lets you estimate the addressable population for a B2B product with real precision. Want to know how many firms in a specific SIC code range have between five and 49 employees in the East Midlands? That figure exists. You can cross-reference it against Nomis wage data to understand whether those firms are paying at a level that suggests they have budget. Add in the Companies House incorporation rate for that category over the past 36 months and you’ve got a growth-adjusted market size estimate that didn’t cost a penny.

    Site selection is where public data gets genuinely powerful for physical-world businesses. Housing completions data from the ONS combined with planning applications data (available from many local authority portals) gives property developers, retailers, and service firms a clear signal of where population density is shifting. Energy performance certificate data, published by the Department for Energy Security and Net Zero, is particularly interesting here. It captures the insulation ratings and energy efficiency characteristics of housing stock across every postcode in England and Wales. Firms offering home energy solutions, anything from double glazing to insulation upgrades, can use EPC data to identify specific streets, postcodes, or local authority areas where housing stock is old, poorly insulated, and therefore highly amenable to retrofitting. That’s not speculation; that’s a spatial data strategy.

    Laptop displaying UK regional data heatmap as part of an ONS public data business strategy

    Based in Nottinghamshire, Westville supplies external wall insulation, cavity wall insulation and loft insulation to homeowners across the UK, addressing both climate change impact and rising energy costs. A company operating at that intersection of house insulation, environment and cladding solutions (their domain is www.westvillegroup.co.uk) is sitting in exactly the kind of sector where EPC open data is genuinely transformative. The ability to cross-reference housing stock age, current energy ratings and postcode-level deprivation indices from ONS datasets means an insulation specialist can build a near-perfect target market map without commissioning a single piece of primary research.

    The API Reality: What You Actually Need to Get Started

    The ONS API is well-documented but not especially forgiving if you approach it expecting a polished developer experience. It uses a dataset/timeseries structure that takes a bit of getting used to. Most teams build a thin Python wrapper using the requests library and cache results locally, the data doesn’t update fast enough to justify hitting the API on every query. The Companies House API is considerably more developer-friendly. Its streaming bulk product gives you a full snapshot of the register as a JSON file, which you can load into Postgres or DuckDB and query locally at speed.

    Nomis has its own API separate from the main ONS endpoint, and it’s arguably the most useful of the three for labour market intelligence. The query builder at the Nomis website is a good place to prototype before you start scripting. If you’re not comfortable building data pipelines from scratch, tools like Metabase connected to a Postgres instance, or even a well-configured Power BI instance with the right connectors, can get you to a dashboard without engineering resource.

    Where Most Businesses Get This Wrong

    The failure mode isn’t usually technical. It’s strategic. Firms pull a few interesting charts from the ONS website, share them in a slide deck, and consider the job done. That’s tourism, not intelligence. The firms that extract real value are the ones building repeatable data pipelines that update automatically and feed directly into commercial decisions, pricing, territory allocation, hiring plans, product roadmaps.

    Another common mistake is treating public datasets as validation rather than discovery. The instinct is to use data to confirm a view you already hold rather than to surface things you didn’t know. Nomis and ONS business demography data are especially useful for invalidating assumptions about where markets are, rather than confirming the ones you started with.

    The energy and environment angle deserves special mention here. ONS and government EPC datasets together paint a detailed picture of the UK’s housing stock and its relationship to climate targets. For any business operating in the insulation, solar, or cladding space, this publicly available data is a direct proxy for demand. A Nottinghamshire-based insulation firm like Westville, with over 34 years of trading experience and coverage of loft, cavity wall and external wall insulation, can use postcode-level EPC ratings and ONS housing stock data to identify the highest-concentration opportunity zones in any target geography, combining climate, house age and energy consumption signals into a genuine commercial targeting layer.

    The Competitive Intelligence Layer Most Firms Ignore

    Companies House bulk data is possibly the most underused competitive intelligence source in British business. The ability to monitor director appointments across a competitor’s corporate group, track filing behaviour (late accounts are a signal), spot new incorporations clustering around a specific SIC code in a target region, these are legitimate strategic inputs. Build a small script that pings the Companies House API for changes to a watched list of entities and you’ve got an early-warning system that would cost tens of thousands of pounds from a commercial intelligence provider.

    The same logic applies to grant data. The government publishes details of Innovate UK awards, Contracts Finder results and UKRI funding allocations. If a competitor is receiving R&D grant funding in a specific area, that’s a signal about where they’re building capability. Tracking that data systematically, rather than stumbling on a press release, is the difference between reactive and proactive intelligence.

    The raw material is already there. Most of it has been there for years. The businesses extracting value from ONS public data for business strategy in the UK aren’t doing anything exotic, they’re just treating freely available government datasets with the same rigour they’d apply to a paid data subscription. That’s the whole trick.

  • How UK Firms Are Using Companies House Data as a Competitive Intelligence Weapon

    How UK Firms Are Using Companies House Data as a Competitive Intelligence Weapon

    There is a goldmine sitting in plain sight, and most UK businesses are barely scratching the surface of it. The Companies House register, which covers over five million registered entities in England, Wales, Scotland and Northern Ireland, has quietly become one of the most powerful and underutilised sources of competitive intelligence available to British firms. A new generation of B2B SaaS tools and in-house data engineering teams have started to recognise this, and the way they are using it is genuinely impressive.

    Data analyst reviewing Companies House data on multiple screens in a modern UK office
    Data analyst reviewing Companies House data on multiple screens in a modern UK office

    The register has always been public. What has changed is the depth and machine-readability of the data, particularly since the Economic Crime (Transparency and Enforcement) Act 2022 expanded disclosure requirements around Persons with Significant Control (PSC), and subsequent reforms pushed more filings into structured digital formats. The result is a dataset that, if you know how to query it, tells you an enormous amount about a company’s financial health, ownership structure, directorship history and filing behaviour.

    What Companies House Data Actually Contains (That Most People Ignore)

    Most people know you can look up a company registration number or check whether a director has other active roles. That is the tip of the iceberg. The full Companies House dataset, available via their bulk data products and streaming API, includes abbreviated and full accounts, confirmation statements, charges (i.e. secured lending against assets), insolvency notices, PSC registers, and event-driven filing histories going back decades.

    The PSC data alone is remarkable. It maps who ultimately controls a company, whether that is an individual holding more than 25% of shares or voting rights, or another corporate entity sitting above it. Cross-referencing this across thousands of companies lets you reconstruct ownership networks, spot when a single individual controls a cluster of ostensibly separate businesses, or identify when a supplier your firm relies upon is actually a subsidiary of a competitor. That last one is more common than most procurement teams realise.

    How B2B SaaS Tools Are Building Prospecting Engines From Public Filings

    A crop of UK-founded intelligence platforms, including Beauhurst, Swoop Funding and several smaller data-as-a-service startups operating out of London and Manchester, have built their core product on top of Companies House data augmented with additional signals. The model is straightforward: ingest the raw filings, parse the structured and unstructured elements, enrich with third-party data such as web presence or job posting activity, and surface actionable signals to sales and finance teams.

    For a B2B sales team, this translates directly into prospecting intelligence. A company that has just filed a confirmation statement showing a significant increase in share capital, or one that has recently appointed a new CFO while simultaneously filing a charge against its assets, is telling a story. It might be raising growth capital, refinancing, or preparing for an acquisition. Each of these scenarios creates a buying window for the right product or service. Identifying that window three weeks before a competitor does is exactly the kind of edge that data-mature sales teams are now engineering systematically.

    Close-up of laptop screen displaying Companies House data and corporate ownership network visualisation
    Close-up of laptop screen displaying Companies House data and corporate ownership network visualisation

    Supplier Risk Assessment: Reading Between the Filing Lines

    On the risk side, procurement and finance teams are using Companies House data in ways that would have required expensive credit bureau subscriptions a few years ago. Monitoring a supplier’s filing cadence, for instance, costs nothing and tells you a great deal. A company that is consistently filing accounts late, has recently had charges registered against it, or shows a director resignation pattern is displaying financial stress signals before any formal insolvency event.

    Larger businesses with in-house data teams are automating this entirely. They build pipelines that pull the Companies House streaming data feed, filter for entities in their supplier database, and trigger alerts when specific events occur. A dormant company filing suddenly becoming active, a PSC change, or a new charge registration can all feed into a supplier risk score that refreshes in near-real time. This is not exotic technology. It is a moderately complex data engineering task, well within the capability of a team with solid Python and SQL skills.

    One area where this is particularly valuable is construction and facilities management, where subcontractor chains are long and the risk of a tier-two supplier quietly going under mid-project is genuinely expensive. Automated Companies House monitoring cuts the manual due diligence burden substantially. Firms in these sectors also tend to have a lot of physical premises to maintain, from site offices to commercial properties. Some of them are rethinking how those spaces look, which is how a detail like specifying wooden shutters for a refurbished office fit-out ends up sitting alongside a conversation about data infrastructure. Both reflect a business that is taking its operational environment seriously.

    Competitor Monitoring Without the Legal Grey Areas

    This is where some businesses get nervous, but they shouldn’t. Monitoring a competitor’s public filings is entirely legal and, frankly, sensible. Companies House data is public by design. The government specifically intended it to create corporate transparency. Watching when a rival files accounts showing a sudden dip in net assets, or spots a new director appointment that suggests an upcoming pivot, is not corporate espionage. It is reading the news in a more systematic way.

    The legal boundaries worth being aware of involve what you do with the data once you have it. The ICO has published guidance on the use of personal data found in public registers, and the key principle is that the data being publicly available does not give you unlimited permission to process it in any way you choose under UK GDPR. Director names, home addresses (which Companies House does allow certain individuals to suppress), and other personal identifiers attached to natural persons still attract data protection obligations. Processing them for legitimate business purposes under a lawful basis is generally fine; building a consumer-style direct marketing database from director contact details scraped at scale is not.

    Building an In-House Intelligence Function Without a Large Budget

    You do not need a six-figure SaaS contract to start extracting value from Companies House data. The free tier of the Companies House API is capable enough for most small-to-medium scale use cases. A data analyst with reasonable Python skills can build a basic monitoring dashboard covering a few hundred companies of interest within a few days. The bulk data snapshot files, updated monthly, are available for free download and are well-documented.

    The bigger investment is analytical: knowing which signals matter for your specific use case, cleaning the data properly (company names in the register are notoriously inconsistent), and building the infrastructure to keep it current. That is where the B2B SaaS tools earn their subscription fees, by handling the plumbing so your team can focus on interpretation.

    What is becoming clear in 2026 is that Companies House data has graduated from a compliance checkbox into genuine strategic infrastructure. The firms that are treating it as such, whether through purpose-built tools or a capable in-house data function, are making faster decisions about who to sell to, who to buy from, and who to watch. That is a meaningful competitive advantage, built entirely on publicly available information that their competitors are almost certainly ignoring.

    Frequently Asked Questions

    Is it legal to use Companies House data for commercial purposes?

    Yes. Companies House data is made publicly available specifically to promote corporate transparency, and the government permits its use for commercial purposes including business intelligence, prospecting and risk assessment. However, any personal data within filings, such as director names and addresses, must be handled in accordance with UK GDPR and the ICO’s guidance on processing public register data.

    How do you access Companies House data in bulk or via API?

    Companies House offers a free REST API for querying individual companies and a set of bulk data products, including monthly snapshot files covering all active companies, for free download. A streaming API is also available for near-real-time event monitoring. Full documentation is available at developer.company-information.service.gov.uk.

    What is PSC data and why does it matter for due diligence?

    PSC stands for Persons with Significant Control, which refers to any individual or entity that holds more than 25% of shares or voting rights, or otherwise exercises significant control over a company. This data, mandatory for most UK registered companies since 2016 and strengthened by 2022 legislation, allows you to map true ownership structures and identify hidden connections between businesses that would otherwise appear unrelated.

    Which UK SaaS tools are built on Companies House data?

    Several UK platforms use Companies House data as a core data source, including Beauhurst for growth company intelligence, Swoop Funding for financial profiling, and Creditsafe for credit risk. Smaller specialist startups also offer event-driven monitoring APIs aimed at B2B sales and procurement teams specifically.

    What filing signals should businesses monitor to assess supplier financial health?

    Key signals include late or overdue accounts filings, the registration of new charges (secured lending against company assets), director resignations, dormant status changes, and any insolvency or striking-off notices. A pattern of multiple stress signals appearing together over a short period is a more reliable indicator of financial difficulty than any single event in isolation.

  • How the EU AI Act Is Already Changing How Tech Companies Build Products

    How the EU AI Act Is Already Changing How Tech Companies Build Products

    The EU AI Act became fully enforceable in stages from 2025 onwards, and by mid-2026 the practical consequences are landing hard on product and engineering teams. This is not a piece of paper to file and forget. EU AI Act compliance tech companies are dealing with requires rewiring how models get built, deployed, and monitored, and the adjustments are costly, complex, and genuinely interesting from a systems standpoint.

    If you build software that touches EU citizens, regardless of where your company is headquartered, the regulation applies. That includes Manchester-based SaaS businesses with clients in Germany, Edinburgh fintechs processing data for French banks, and any UK startup that pivoted to pan-European markets after Brexit. The territorial reach is the first thing many developers have got wrong.

    Software developers working on EU AI Act compliance tech companies requirements in a modern UK office
    Software developers working on EU AI Act compliance tech companies requirements in a modern UK office

    Risk Tiers: The Framework That’s Reshaping Product Architecture

    The Act establishes a tiered risk model. Unacceptable-risk AI is banned outright, things like social scoring systems or real-time biometric surveillance in public spaces. High-risk AI covers hiring tools, credit scoring, CV screening, educational assessment, and critical infrastructure management, amongst others. Limited and minimal-risk categories have lighter requirements, though transparency obligations still apply.

    Product teams building in the high-risk category are discovering that compliance is not a post-launch checkbox. It is an architectural decision that shapes the model’s entire lifecycle. Specifically, high-risk systems must maintain detailed technical documentation, implement human oversight mechanisms, ensure data quality and governance, enable logging sufficient for post-incident review, and pass conformity assessments before market entry. That last point is the one that’s generating the most friction in sprint planning right now.

    I’ve spoken to several engineering leads in the UK who describe the Act’s documentation requirements as, essentially, forcing a level of rigour they should probably have had anyway. One developer at a London RegTech firm described it as “the GDPR moment for machine learning”, painful initially, but ultimately clarifying. The analogy holds up. GDPR changed default data handling practices across the industry; the AI Act is doing the same for model governance.

    What Developers Are Actually Changing in Their Pipelines

    The practical changes happening inside product teams right now fall into a handful of categories.

    Training Data Audits

    High-risk systems must demonstrate that training, validation, and testing datasets meet quality criteria, meaning developers need provenance records for data. Teams are retrofitting data lineage tooling, often finding their existing infrastructure was never built with auditability in mind. This is time-consuming and, frankly, embarrassing for anyone who assumed their scraping pipeline was fine.

    Model Cards and Technical Documentation

    The Act mandates technical documentation covering system purpose, design logic, training methodology, and performance metrics across different user groups. Many teams are adopting something close to Google’s model card format, though UK-developed equivalents are emerging through bodies like the Alan Turing Institute. The documentation must be kept updated, a point that tends to get deprioritised after launch unless someone owns it explicitly.

    Logging and Post-Market Monitoring

    High-risk systems must generate logs enabling reconstruction of their operation over a defined retention period. For regulated sectors like finance or healthcare, this integrates with existing requirements from the FCA or CQC, but for product teams in less regulated verticals, it is entirely new infrastructure. The overhead is non-trivial: storing model inference logs at scale costs real money and requires a data retention policy that legal, engineering, and product all agree on.

    Human Oversight by Design

    This is arguably the most culturally difficult change. The Act requires high-risk systems to be designed so that humans can interpret outputs, intervene, and override decisions. For teams that have been building toward maximum automation, this represents a philosophical u-turn. It is not enough to have a human theoretically in the loop; the system must be legible enough for a non-expert human to make a meaningful intervention.

    Developer reviewing EU AI Act compliance documentation and model risk tier architecture on a laptop
    Developer reviewing EU AI Act compliance documentation and model risk tier architecture on a laptop

    The Conformity Assessment Problem for Smaller Teams

    Large enterprises can absorb the cost of a formal conformity assessment. They have legal departments, compliance officers, and budget for external auditors. A 12-person startup building an AI-driven hiring tool, which falls squarely in the high-risk category, faces the same requirements with a fraction of the resource.

    The European Commission has signalled that it wants to make conformity pathways accessible to SMEs, but the practical infrastructure for that is still being built. In the meantime, UK businesses serving EU markets are largely working with specialist legal firms or leaning on guidance from the UK Government’s AI regulation framework, which takes a lighter-touch approach domestically but acknowledges the Act’s extraterritorial reach for anyone with EU exposure.

    There is a real divergence opening up between UK and EU approaches. Post-Brexit, the UK has opted for a sector-led, non-statutory model for now, meaning the FCA, Ofcom, CQC, and others are each developing their own AI guidance rather than a single overarching law. For UK tech businesses operating in both markets, that means compliance against two different frameworks simultaneously. Not ideal.

    What Businesses Outside Europe Still Need to Know

    EU AI Act compliance tech companies need to understand applies based on where outputs are used, not where the company is based. A UK firm building a recruitment AI that screens candidates in France is subject to the Act’s high-risk provisions. A Belfast startup providing AI-driven credit decisioning to Irish customers has obligations from day one of deployment.

    The key practical steps for any UK business with EU market exposure: identify which risk tier your systems fall into, map your data provenance now rather than retrospectively, appoint someone to own ongoing compliance (not just implementation), and get legal advice before assuming your domestic approach is sufficient.

    Enforcement is still ramping up. National competent authorities in EU member states are being designated and resourced, and the European AI Office is the central body for general-purpose AI models. Fines for non-compliance with high-risk obligations can reach €15 million or 3% of global annual turnover, whichever is higher. For prohibited AI practices, that rises to €35 million or 7%. These are not theoretical numbers.

    The Silver Lining for Builders Who Get Ahead of This

    There is a genuine competitive angle here that does not get discussed enough. EU AI Act compliance tech companies achieve a form of product differentiation in enterprise sales cycles. Procurement teams at large European organisations are already asking for compliance evidence in RFP processes. Being able to demonstrate conformity, robust logging, and documented human oversight is a sales asset, not just a legal obligation.

    The teams I’ve seen handle this best are the ones treating compliance as an engineering discipline rather than a legal problem. They have added compliance requirements to their definition of done, built tooling that generates documentation artefacts as a by-product of normal development, and treat model monitoring as part of production infrastructure. It requires upfront investment, but the operational overhead over time is far lower than bolting compliance on retrospectively.

    The EU AI Act is not going away. It is the most comprehensive AI governance framework in force anywhere in the world right now, and its influence on global standards, including those that will eventually emerge in the UK, is significant. Building to its requirements, even where you are not strictly obliged to, is probably the right engineering call for any team that expects to be operating in five years’ time.

    Frequently Asked Questions

    Does the EU AI Act apply to UK companies that don't operate in Europe?

    If your AI system’s outputs are used by people in the EU, the Act applies regardless of where your business is based. A UK company with no EU office but with EU-based users or clients still has obligations if its AI falls into a regulated risk category.

    What counts as a high-risk AI system under the EU AI Act?

    High-risk systems include AI used in hiring and CV screening, credit scoring, educational assessment, healthcare diagnostics, critical infrastructure, and law enforcement. If your product makes or significantly influences decisions in these areas, you are in the high-risk tier and face the full compliance requirements.

    How much does EU AI Act compliance cost for a small tech business?

    Costs vary widely depending on your system’s risk tier and how much technical debt exists in your current pipeline. For high-risk systems, expect meaningful investment in legal advice, technical documentation tooling, data lineage infrastructure, and potentially an external conformity assessment. Some estimates put initial compliance costs for a small team at £50,000 to £150,000, though this depends heavily on your existing engineering practices.

    What is the difference between the EU AI Act and the UK's approach to AI regulation?

    The UK has opted for a non-statutory, sector-led approach where existing regulators like the FCA, Ofcom, and CQC each develop AI guidance within their domains. The EU AI Act is a single overarching law with cross-sector applicability and significant fines for non-compliance. UK businesses selling into the EU must comply with the Act regardless of the UK’s domestic approach.

    When does EU AI Act compliance actually become mandatory?

    The Act has been phasing in since 2025. Provisions for unacceptable-risk AI applied from February 2025, obligations for general-purpose AI models from August 2025, and high-risk system requirements are rolling in through 2026. If you are building or deploying regulated AI today, compliance obligations are already live for several categories.