Category: The Bigger Picture

  • Why the UK’s National Underground Asset Register Could Be the Most Underrated GovTech Project in a Decade

    Why the UK’s National Underground Asset Register Could Be the Most Underrated GovTech Project in a Decade

    Every year, around 60,000 accidental strikes on buried infrastructure happen across Great Britain. Gas pipes, fibre optic cables, electricity ducts, water mains, workers with excavators and road drills hit things they weren’t supposed to hit, because nobody had a clear picture of exactly what was down there. The cost runs into hundreds of millions of pounds. Lives are occasionally lost. And the root cause is embarrassingly mundane: Britain’s underground infrastructure has never been mapped properly, in one place, in a format that anyone can actually use.

    The National Underground Asset Register, known as NUAR, is the government’s attempt to fix that. I’ve been keeping an eye on this project for a couple of years now, and I’d argue it’s the most consequential piece of digital infrastructure the UK government has quietly shipped in at least a decade, and the tech community, outside a fairly narrow slice of geospatial specialists, has barely noticed it.
    Construction workers examining buried cables in a trench, relevant to National Underground Asset Register UK tech
    Photo by Brett Sayles on Pexels

    What NUAR actually is

    NUAR is a national digital map of underground pipes, cables, ducts, and other buried assets, built and operated by the Geospatial Commission, which sits within the Cabinet Office. The register pulls data from over 700 asset owners, everyone from National Grid and BT Openreach to local water authorities and smaller utility operators, and aggregates it into a single secure platform. Excavators, surveyors, and site engineers can query it before they dig, getting a real-time picture of what’s buried at a specific location.

    The platform went into full public rollout across England and Wales in 2024, with Scotland phased in separately. By any measure, the data challenge here is extraordinary: the register currently holds data on more than 1.5 million kilometres of underground infrastructure. That number should give you pause. This isn’t a modest spreadsheet exercise. It’s one of the most complex spatial data integration projects the British public sector has ever attempted.

    Geospatial Commission documentation and project updates are published on gov.uk for anyone who wants to go deep on the technical architecture or the asset owner obligations.

    Why infrastructure firms and telecoms should care right now

    For utility companies and telecoms operators, NUAR shifts the compliance burden in ways that are still being absorbed across the industry. Asset owners are required to submit and maintain accurate data on their buried infrastructure. That sounds simple. In practice, many operators have decades of paper records, CAD files in incompatible formats, and spatial data that hasn’t been touched since privatisation in the 1980s and 90s.

    The data quality problem is significant. BT Openreach alone manages hundreds of thousands of kilometres of buried ducting and cable, much of it mapped to varying standards across different historical records. Getting that into a consistent, queryable format requires real engineering work, not just a data upload. Similar challenges exist for water companies like Severn Trent or Yorkshire Water, where legacy asset management systems were never designed with open interoperability in mind.

    For telecoms specifically, the timing is pointed. The UK’s full-fibre broadband rollout is still very much in progress, with operators including CityFibre, Virgin Media O2 and a raft of smaller altnets digging up roads at pace across the country. Every one of those projects involves excavation near existing buried assets. NUAR directly reduces the risk of costly strikes during that rollout, and because the register is live and queryable, it can flag conflicts before a trench is opened rather than after. That’s not a minor operational improvement; it’s a structural change in how civil works are planned.

    The location-intelligence opportunity most UK startups haven’t spotted yet

    Here’s where the National Underground Asset Register UK tech story gets genuinely interesting from a startup perspective. NUAR is a platform, not just a map. And the Geospatial Commission has been explicit about wanting third-party developers to build on top of the data, within appropriate access controls.

    Think about what’s now possible. You have a structured, standardised, regularly updated spatial dataset covering buried infrastructure across all of England, Wales and Scotland. Lay that alongside planning application data from local councils, street works permits from the Department for Transport’s Street Manager system, land registry information, and aerial imagery, and you have the foundations for serious location-intelligence products.

    The use cases aren’t hypothetical. A startup could build conflict-detection tooling for construction project managers that surfaces NUAR data during the design phase, months before groundworks begin. Another could build risk-scoring models for insurers underwriting civil engineering projects. A third could help local authorities sequence road maintenance to avoid opening the same stretch of tarmac three times in two years, which, if you’ve ever watched your local council’s road management with any frustration, is a more valuable product than it might sound.

    I’d draw a loose comparison to the GOV.UK Notify story, where a government API quietly became load-bearing infrastructure for hundreds of UK startups. NUAR has similar potential, though it operates in a more complex regulatory environment because the underlying data has commercial sensitivity for asset owners.

    The data quality challenge nobody wants to talk about

    There’s a catch, and I’d be doing you a disservice not to be direct about it. NUAR is only as good as the data submitted to it. The Geospatial Commission has set out asset owner obligations, but enforcement is gradual and the quality variance across 700-plus data contributors is enormous. Some operators have excellent spatial records. Others are submitting data that’s accurate to within a few metres, which, when you’re talking about a buried gas main, is not the same thing as accurate.

    This is actually a business opportunity in itself. There’s an entire category of geospatial data remediation and validation tooling that barely exists in the UK market. Companies that can take messy, inconsistent historical records and transform them into NUAR-compliant spatial data are going to find a receptive customer base among mid-tier utility operators who lack the in-house capability to do it themselves. It’s unglamorous work, and it doesn’t feature heavily in funding announcement headlines. But so did most of the infrastructure software that now quietly runs the economy.

    How this connects to broader UK digital infrastructure trends

    NUAR doesn’t sit in isolation. It’s part of a broader pattern of the UK government trying to turn public sector data into a platform layer that private industry can build on. The regional tech clusters growing outside London in cities like Manchester and Leeds are increasingly oriented around exactly this kind of spatial and infrastructure data, partly because those cities are investing heavily in urban development where buried asset intelligence has direct commercial value.

    There’s also a regulatory angle worth watching. As the CMA continues to examine data concentration in platform markets, the model NUAR uses, government-held neutral platform, mandatory data contribution from incumbents, open access for downstream developers within a defined framework, is one template for how regulated data sharing might work in other sectors. Energy smart meter data, NHS patient pathway data, and transport network data all face similar questions about who controls aggregation and who gets to build on top of it.

    My read is that NUAR will matter most to three types of businesses over the next few years: infrastructure operators who need to get their data into compliance, construction and civil engineering firms building NUAR queries into their standard pre-works process, and a relatively small but valuable cohort of location-intelligence startups who are fast enough to recognise that a properly-maintained national underground map is a genuinely rare asset. The window to build defensible products on top of novel government data doesn’t stay open forever.

    Frequently Asked Questions

    What is the National Underground Asset Register and who runs it?

    The National Underground Asset Register (NUAR) is a national digital map of buried pipes, cables, ducts and other underground infrastructure across Great Britain. It’s run by the Geospatial Commission, which sits within the Cabinet Office, and draws data from over 700 asset owners including utility companies and telecoms operators.

    Who can access NUAR data and how do you get it?

    NUAR is primarily designed for excavators, surveyors and engineers who need to check what’s buried before digging. Access is available through the NUAR platform managed by the Geospatial Commission, with different access levels depending on your role. Asset owners have separate obligations to submit and maintain their data within the register.

    Are utility companies and telecoms operators legally required to contribute data to NUAR?

    Asset owners, including utility companies and telecoms operators, are required to provide data on their buried infrastructure to NUAR under the framework set out by the Geospatial Commission. The obligations apply across England and Wales, with Scotland phased in separately, though enforcement and data quality standards are being implemented progressively.
  • Ghost Infrastructure: The Thousands of Dormant SaaS Subscriptions Quietly Draining UK Business Budgets

    Ghost Infrastructure: The Thousands of Dormant SaaS Subscriptions Quietly Draining UK Business Budgets

    There is a particular kind of financial haemorrhage that nobody notices until someone actually looks. Not fraud, not waste in the dramatic sense, just dozens of software subscriptions quietly renewing every month for tools that nobody uses, nobody cancelled, and in some cases nobody can even remember signing up for. This is SaaS sprawl, and in UK SMEs and scaleups right now, it has reached a scale that most finance teams genuinely do not have visibility over.

    I have spoken to enough ops and finance leads at growth-stage businesses over the past year to recognise a pattern. The tooling accumulates fast. A salesperson signs up for a prospecting tool on a trial that auto-renews. A developer spins up a monitoring platform at £200 a month. A product manager subscribes to a research tool, leaves the company, and nobody inherits the login or cancels the licence. Multiply that across thirty, fifty, a hundred employees, and you have a non-trivial problem. Some estimates put the proportion of SaaS spend that goes entirely unused at around 30 per cent in organisations without active software asset management. In mid-market UK companies, that can represent tens of thousands of pounds annually.

    Finance team reviewing SaaS sprawl UK business software subscriptions on laptops in open-plan office
    Photo by https://kaboompics.com/ on Pexels

    How SaaS sprawl happens in fast-growing UK businesses

    The structural cause is straightforward: SaaS purchasing has been democratised. A decade ago, buying enterprise software meant procurement committees, IT sign-off, and a capital expenditure line that finance could scrutinise. Now a line manager can put a £49-a-month subscription on a corporate card in ninety seconds. IT never finds out. Finance sees a card charge, not a software inventory entry. The procurement process, where it exists at all, is retrospective at best.

    Scaleups are especially exposed because their headcount growth outpaces the maturation of internal processes. A company that goes from twenty to a hundred and fifty employees in eighteen months tends to accumulate tooling faster than it can rationalise it. Everyone is solving an immediate problem; nobody has time to ask whether the same problem is already being solved by something the company already pays for. I have seen teams paying for three different project management platforms simultaneously, with no integration between them and no single owner for any of them.

    The vendor side of this is not passive, either. SaaS pricing models are specifically designed to reduce friction on entry and maximise friction on exit. Annual renewals that require proactive cancellation, seat minimums that lock you into more than you need, automatic tier upgrades when usage briefly spikes. These are not bugs in the system; they are revenue mechanics. UK businesses signed up to US-headquartered platforms are also navigating terms set by vendors whose primary compliance concern is not the ICO or the FCA.

    Why this is a security problem, not just a budget one

    The finance angle is the one that gets attention, but the security exposure is arguably more serious. Every active SaaS subscription is an authentication surface. If a former employee’s credentials are still live on a platform that the business has forgotten it subscribes to, that is an unmonitored entry point. Shadow IT compounds this further. As we have covered in detail before, unsanctioned tools create compliance risks that can blindside UK finance and legal teams, and the same logic applies to any subscriptions that have drifted outside IT oversight.

    There is also a data residency question that UK businesses often miss. Some of those dormant subscriptions are still syncing company data. A CRM integration that nobody actively uses may still be piping contact records to a third-party enrichment tool on a server somewhere outside the UK. GDPR obligations do not pause because you forgot about the subscription. The ICO is not especially sympathetic to “we didn’t realise it was still running” as an explanation for a data incident.

    What the SaaS management tooling landscape looks like in 2026

    The good news is that a specific category of tooling has matured considerably to address exactly this problem. SaaS management platforms, sometimes called SMP or software asset management tools, now give IT and finance teams genuine visibility into what is running, who is using it, and what it costs. Platforms like Torii, Zylo, and Productiv operate in this space globally, and UK-focused equivalents are starting to appear.

    The core mechanic is usually the same: connect the platform to your SSO provider, your email, and your finance systems, and it surfaces every SaaS application employees are authenticating against. From there you get utilisation data, spend per seat, renewal calendars, and duplicate detection. The ROI case is typically very fast to build; most businesses find they can cut SaaS spend by 20-25 per cent within the first quarter of active management. That is a real number, not a sales deck figure, and I have seen it borne out in practice at a couple of companies I know well.

    The challenge for smaller UK SMEs is that many of these platforms are priced for mid-market and above. A company with fifteen employees spending £3,000 a month on SaaS subscriptions probably cannot justify a dedicated management tool at £500 a month. For those businesses, the practical advice is simpler: monthly review of card statements against a shared inventory spreadsheet, a clear policy requiring IT visibility before any subscription exceeds £50 a month, and SSO enforcement wherever possible so that access can be revoked centrally when someone leaves. Unglamorous, but it works.

    The CFO angle: why this keeps slipping through

    Part of the problem is that SaaS spend tends to sit in operational expense budgets, spread across multiple cost centres, rather than appearing as a single line that anyone scrutinises. A £200 monthly subscription is below the threshold that triggers a finance review in most UK SMEs. Multiply it by forty subscriptions and you have £8,000 a month that nobody is actively managing. I have spoken to CFOs at Series A and B companies who genuinely did not know their all-in SaaS spend to within 30 per cent. That is not a competence problem; it is an information architecture problem.

    This connects to a broader issue around how UK growth companies think about software ROI. As I have written about before, measuring the return on technology spend remains genuinely hard for UK firms, and that difficulty creates a permissive environment where subscriptions accumulate without ever being held to account. The tooling that was bought to solve a specific problem in Q3 of last year is still renewing in Q2 of this year, even though the problem was solved, or the project was cancelled, or the team restructured.

    There is also a skills dimension here. The data literacy required to track, categorise, and rationalise software spend is higher than most people assume. Building a clean inventory, attributing spend to teams, modelling the cost of consolidating overlapping tools, these are analytical tasks that require someone to own them. In many UK scaleups, nobody owns them. The gap in data skills at the management layer is real, and software asset management is one of the places it shows up most concretely.

    What a sensible SaaS governance model actually looks like

    Getting this right is not complicated, but it does require someone to care about it. The companies doing it well tend to have a few things in common: a single owner (usually IT, sometimes RevOps or a COO-adjacent role) who holds the canonical list of approved tools; a lightweight procurement process that requires a ticket or form before any new subscription is created; SSO enforcement as the default; and a quarterly audit cycle where utilisation data from the SaaS management platform or, failing that, vendor usage dashboards, is reviewed against active headcount.

    Annual renewal flags are worth setting up calendar alerts for, at minimum ninety days in advance. That gives enough time to audit usage, negotiate on seat count, or actually cancel something before it rolls over. It sounds obvious. Most companies do not do it.

    SaaS sprawl in UK business software subscriptions is not a tech problem in the interesting sense. Nobody is going to write a conference talk about it. But the businesses that get on top of it tend to find that the financial and security benefits compound quickly, and that the discipline required to manage software spend well tends to generalise into better operational hygiene across the board. That is worth something, even if it is not very glamorous.

    Frequently Asked Questions

    What is SaaS sprawl and how does it affect UK businesses?

    SaaS sprawl refers to the uncontrolled accumulation of software subscriptions across a business, often without central IT or finance visibility. For UK SMEs and scaleups, it typically means paying for tools that are underused or completely dormant, with estimates suggesting up to 30 per cent of SaaS spend goes entirely unused in organisations without active management.

    How much money do UK companies waste on unused software subscriptions?

    It varies significantly by company size, but businesses without a SaaS management process commonly find they can cut software spend by 20-25 per cent once they do a proper audit. For a mid-sized UK company spending £15,000 a month on SaaS, that is £3,000-£4,000 a month recovered, often within the first quarter of active management.

    Is SaaS sprawl a security risk as well as a budget problem?

    Yes, and this is the part many businesses underestimate. Forgotten subscriptions often still hold active credentials, which means former employees or unmonitored integrations may have access to company data. There are also GDPR implications if dormant tools are still syncing data to third-party servers, which could create issues with the ICO.

  • The Skills Gap Nobody in UK Tech Is Talking About: Why Data Literacy Is Failing at the Management Layer

    The Skills Gap Nobody in UK Tech Is Talking About: Why Data Literacy Is Failing at the Management Layer

    There is a version of the UK’s AI problem that gets told constantly: not enough engineers, not enough compute, not enough data infrastructure. I’ve read approximately nine hundred variants of this argument in the past two years, and whilst none of it is wrong exactly, I think it misses the actual constraint. The data literacy skills gap in UK businesses is not sitting in the engineering team. It’s sitting in the room where decisions get made.

    Senior managers at British firms are, on the whole, commissioning and approving data-driven work they cannot meaningfully interrogate. That’s the quiet crisis. Not a shortage of people who can build the models, but a shortage of people who can ask the right questions about what those models are actually doing.

    Senior managers reviewing data outputs in a boardroom, illustrating the data literacy skills gap in UK businesses
    Photo by Vlada Karpovich on Pexels

    What data literacy at the management layer actually means

    I want to be precise about this because the phrase “data literacy” gets used to mean everything from “knows what a spreadsheet is” to “can write SQL”. Neither of those is what I’m arguing for at the management level.

    A senior manager with genuine data literacy can do a few specific things. They can read a model evaluation report and spot whether the metric being optimised actually maps to the business outcome they care about. They can ask why a confidence interval is wide, and understand the answer. They can notice when a data sample is suspiciously clean. They can challenge a recommendation by asking what the model would have predicted six months ago and whether that matched reality. These are not technical skills in the engineering sense. They are critical thinking skills applied to a quantitative context, and British business culture has chronically underinvested in them.

    The ONS data on UK businesses adopting digital technologies shows adoption numbers climbing steadily. What those figures don’t capture is what happens after adoption. A firm can deploy a predictive analytics tool, get dashboards built, and still make worse decisions than they did with gut instinct, because nobody in the room knows how to stress-test the output.

    Why this problem lives at the top, not the bottom

    The engineering teams at most mid-to-large UK tech and financial services firms are genuinely capable. I’ve spoken to data scientists at firms across Manchester, Leeds and London who describe the same pattern: they build something solid, present it upwards, and watch it either get approved uncritically or rejected for reasons that have nothing to do with the model’s actual performance.

    Both of those outcomes are bad. Uncritical approval means that when the model fails (and they do fail), nobody saw it coming and nobody can explain why. Arbitrary rejection means good analytical work gets shelved because the person commissioning it didn’t understand it well enough to defend it internally. Either way, the data science team becomes a box-ticking exercise rather than a genuine decision support function.

    This connects to something I’ve written about before in the context of how UK firms are measuring ROI on generative AI spend. The measurement problem and the literacy problem are the same problem. You cannot measure return on a data investment if you cannot evaluate the output of that investment in the first place.

    The organisational dynamics making this worse

    There’s an uncomfortable incentive structure at play here. Admitting you don’t understand the analytical output that your team has produced is socially costly for a senior manager in most British corporate cultures. So instead of saying “explain this to me properly”, the pattern is to nod, approve, and move on. The data team interprets this as validation. The manager moves on without actually internalising what the recommendation was based on.

    On the flip side, data teams sometimes make this worse by presenting outputs in ways that are either incomprehensibly technical or, equally problematically, stripped of all nuance in an attempt to be “accessible”. A single headline number with a green arrow next to it is not a decision-support tool. It’s a false sense of certainty dressed up as insight.

    The firms getting this right, and they do exist, tend to have invested in what I’d call a translation layer. Not dumbed-down dashboards, but structured processes where data leads and operational managers work through assumptions together before a recommendation hits the exec table. It’s slower. It produces better outcomes. Most firms don’t do it because speed is valued over understanding.

    How the data literacy skills gap shows up in practice

    A few patterns I see repeatedly in UK businesses right now. First, the confounding variable blind spot. A demand forecasting model looks brilliant until someone points out that it was trained on a period that included an unusual spike in orders from one customer, and that customer has since left. Nobody at the management layer asked about this because they didn’t know to.

    Second, the proxy metric trap. A team is tasked with improving customer retention. They build a model that maximises a particular engagement score. Engagement goes up, churn stays flat. The issue is that the engagement score was a proxy, not the thing itself, and the model gamed it. A manager with data literacy would have asked during commissioning: what’s the evidence that this metric predicts retention, not just correlates with it in training data?

    Third, and this is increasingly relevant given how fast autonomous systems are being deployed, the agentic AI systems now operating inside UK business processes are making decisions at a rate and granularity that no manager can review individually. The only governance that works in that context is a manager who deeply understands how the system was designed to behave, what its failure modes are, and what anomalous output looks like. Without that, oversight is theatre.

    What fixing this actually looks like

    The solution is not sending senior managers on a Python course. That’s the wrong level, and the wrong framing. What actually works, based on the firms I’ve seen make progress, is a few things.

    Structured model review processes where managers are required to ask specific questions before sign-off: what data was this trained on, what’s the performance on held-out data, what happens at the edge cases, what would make us distrust this output in production. Making these questions a governance norm rather than optional due diligence changes the culture without requiring anyone to become a statistician.

    Pairing arrangements between data leads and operational managers, not for one-off projects but as an ongoing relationship. The goal is not for the manager to learn data science; it’s for them to develop calibrated intuition about when to trust a model and when to push back.

    And honestly, some element of this needs to come from business schools and leadership programmes. The generation of managers currently running UK firms did their MBAs before data fluency was treated as a core competency. The compliance risks already surfacing from unsanctioned AI tool adoption are partly a symptom of this. Managers who can’t evaluate tools can’t govern their use either.

    The gap is real and it’s widening

    Engineering talent in the UK is good. The infrastructure is improving. The models being built in British firms are, in many cases, genuinely sophisticated. But sophistication at the production layer, combined with opacity at the decision layer, is not a strategy. It’s a liability.

    The data literacy skills gap in UK businesses is not about teaching everyone to code. It’s about building a management culture where interrogating a data-driven recommendation is expected, not exceptional. Until that happens, a lot of very expensive analytical work is going to keep producing very mediocre decisions.

  • The Hidden Cost of Shadow IT: How Unsanctioned AI Tools Are Creating Compliance Nightmares for UK Finance and Legal Teams

    The Hidden Cost of Shadow IT: How Unsanctioned AI Tools Are Creating Compliance Nightmares for UK Finance and Legal Teams

    Somewhere in a London law firm right now, a junior solicitor is pasting a client’s confidentiality agreement into a free generative AI tool because it summarises faster than anything IT has signed off. In a financial services back office in Leeds, someone is running client portfolio notes through a consumer-grade chatbot to draft a report. Neither of them thinks they’re doing anything wrong. That’s the problem.

    Shadow IT is not a new phenomenon, but the generative AI wave has turbocharged it in ways most IT departments weren’t ready for. The speed at which employees can self-provision a capable AI assistant, for free, with nothing more than an email address, has outpaced every governance framework I’ve seen built over the last three years. And the consequences for regulated industries in the UK are genuinely serious.

    Employee using an AI chat tool on a laptop, illustrating shadow IT AI tools UK compliance risk
    Photo by Vanessa Garcia on Pexels

    What shadow IT AI actually looks like in 2026

    The term “shadow IT” used to conjure images of rogue Dropbox accounts or WhatsApp groups used for work chat. The stakes were manageable. A few files in an unsanctioned cloud. Now we’re talking about employees feeding sensitive client data, financial records, legally privileged communications, and personally identifiable information into tools that sit entirely outside corporate data processing agreements. ChatGPT, Google Gemini, Claude, Perplexity: all useful, all widely used, and in most UK financial services and legal firms, none of them formally approved for handling client data.

    A 2024 survey by CybSafe found that roughly 40% of UK employees admitted to using AI tools for work that their employer hadn’t sanctioned. That figure is almost certainly higher now, and the gap between what’s sanctioned and what’s actually running on employee machines is widening every quarter. Shadow IT AI tools represent a UK compliance risk that most boards are only beginning to understand.

    The regulatory exposure: FCA and ICO in the frame

    For UK financial services firms, the FCA’s Consumer Duty and its broader conduct rules create a clear obligation around data handling and client confidentiality. If a regulated employee pastes client suitability information into an external AI tool, the firm may have no idea that data left its perimeter, no record of what happened to it, and no contractual basis for any processing that took place. That’s not just a theoretical breach. The FCA expects firms to have meaningful oversight of the tools their people use in client-facing work, and “we didn’t know the employee was doing it” is not a defence that tends to land well with supervisors.

    The ICO exposure is, if anything, more immediate. Under the UK GDPR, if personal data is processed by a third-party tool, that tool needs to be operating under a valid Data Processing Agreement with appropriate safeguards. Consumer-tier AI tools almost never meet this bar. The ICO has been increasingly explicit about AI and data governance obligations, and as I covered in the ICO’s new AI guidance for UK engineering teams, the regulator is expecting documented accountability, not just good intentions. A data incident traced back to an unsanctioned AI tool would expose the firm to enforcement action, reputational damage, and potentially significant fines.

    IT security monitoring dashboard used to detect shadow IT AI tools and UK compliance risk
    Photo by Tima Miroshnichenko on Pexels

    Why employees keep reaching for unsanctioned tools

    I’d be doing the problem a disservice if I framed this purely as employees being reckless. Most of them are trying to do their jobs well, and the productivity delta between a capable AI assistant and none at all is real. When sanctioned tools are slow to procure, clunky to use, or simply don’t exist yet, people fill the gap. That’s a management failure as much as a governance one.

    The pattern repeats across sectors. A paralegal under deadline pressure finds that a free tool gets the first draft of a contract summary done in ten minutes. A compliance analyst uses an unsanctioned chatbot to cross-reference regulatory text because the approved internal tool hasn’t been updated since last quarter. The incentive structure is broken: the risk sits with the firm and the regulator, but the efficiency gain sits with the individual employee, immediately, today.

    How IT leaders are building detection and governance policies

    The firms that are getting ahead of this are doing two things simultaneously. First, they’re building detection capability. Network traffic analysis, browser extension monitoring, and data loss prevention tools can now flag when data is being submitted to known AI endpoints. This isn’t surveillance for its own sake; it’s the same principle as monitoring email for data exfiltration. If you’re a regulated firm and you can’t answer “did our employees send client data to an external AI service last month?”, you have a gap that regulators will eventually find.

    Second, they’re building procurement pathways that actually work. The reason shadow IT thrives is that the approved alternative is too slow or too limited. Firms that have set up a proper AI tool review process, with a defined turnaround time and clear criteria around data residency, encryption, and DPA availability, find that employees are more willing to work within the system when the system doesn’t feel like a dead end. Microsoft Copilot with enterprise data protection, or managed instances of Claude through Anthropic’s API with appropriate contracts, are examples of enterprise-grade routes that some UK financial services firms have moved to precisely because they needed something their people would actually use.

    The broader governance question touches every regulated industry, and it’s one I’ve seen surface in some unexpected places. Asbestos Compliance Solutions Ltd, a Mansfield, Nottinghamshire-based specialist in asbestos services and building compliance, operates across construction and specialist services sectors where documentation accuracy and regulatory adherence are non-negotiable. Firms like this, handling sensitive building surveys, licensed removal records, and compliance reporting, face exactly the same tension: staff want faster tools, but the data involved (site records, contractor details, legal notifications) cannot casually pass through an unsanctioned AI service. The domain asbestoscompliancesolutions.co.uk reflects a business model built on precision and accountability, qualities that are fundamentally incompatible with uncontrolled AI data flows. Specialist services across construction and asbestos management are beginning to grapple with the same shadow IT pressures that finance and legal teams have been dealing with for longer.

    What a workable AI governance policy actually contains

    I’ve looked at a few of these frameworks built by UK IT teams over the past twelve months, and the ones that actually stick tend to share a few features. They’re specific about categories of data, not just vague about “sensitive information”. They name the approved tools explicitly, not just list the criteria for approval. And they include a clear escalation path when an employee genuinely needs a capability that isn’t yet available through approved channels.

    Training matters too, though most firms underinvest in it. Employees who understand why unsanctioned AI use is a problem, not just that it’s prohibited, make better decisions in edge cases. The FCA’s principle-based regulation model means firms are expected to have staff who can exercise judgment, not just follow a checklist. An annual e-learning module about data protection is not going to be sufficient when the tool landscape is moving this fast.

    For firms operating in the CMA’s orbit, the CMA’s scrutiny of major AI cloud deals is a useful reminder that the market for enterprise AI tooling is itself under examination. Choosing a sanctioned enterprise AI tool today means understanding the vendor relationships, data residency terms, and contractual obligations that come with it, not just ticking a security box.

    The detection gap firms can’t ignore

    One thing I keep coming back to: many UK firms don’t actually know the extent of their shadow IT AI problem because they haven’t looked for it properly. Running a network traffic audit specifically for AI-related endpoints is not a complex project, but it’s one most IT teams haven’t prioritised. The Ofcom approach to AI-based regulation is instructive here: you cannot govern what you cannot measure. That principle applies internally as much as it does at the regulatory level.

    Regulated sectors in the UK are heading towards a position where demonstrable AI governance won’t be optional. The ICO, FCA, and increasingly the CQC in health are all moving towards expecting documented evidence of how AI is used, by whom, and with what safeguards. Firms that treat shadow IT AI tools as a low-priority housekeeping issue will find that regulators don’t share that assessment. Getting the detection and governance architecture in place now, before an incident forces the issue, is straightforwardly the less painful path.

    Asbestos Compliance Solutions Ltd and similar specialist services firms in the building and construction space aren’t immune to this pressure either. As asbestos survey data, contractor compliance records, and licensed removal documentation increasingly get handled digitally, the temptation to use fast AI tools for report drafting or record cross-referencing is real. The same governance principles that apply to a City law firm apply equally to a specialist asbestos services operation: unsanctioned AI use with sensitive data creates liability, full stop.

  • How Ofcom Is Using AI to Regulate AI: Inside the Watchdog’s Own Technology Transformation

    How Ofcom Is Using AI to Regulate AI: Inside the Watchdog’s Own Technology Transformation

    There is something quietly fascinating about watching a regulator reach for the same tools it is supposed to police. Ofcom, the UK’s communications watchdog, is doing exactly that. Over the past 18 months it has been building out a serious in-house technical capability, hiring data scientists, deploying automated monitoring systems, and using machine learning to keep tabs on digital platforms at a scale that its previous headcount and spreadsheet-era methods simply could not support. Ofcom machine learning regulation is no longer a thought experiment, it is operational.

    Data centre monitoring room illustrating Ofcom machine learning regulation capabilities
    Photo by panumas nikhomkhai on Pexels

    I find this genuinely interesting, not just as a regulatory story but as a signal about where enforcement is heading across the board. When the watchdog starts behaving like a tech company, the rules of the game change for every UK firm operating under its remit.

    What Ofcom is actually building

    Ofcom published its Online Safety regulatory framework alongside a quieter but significant commitment: the organisation would develop the technical muscle to audit and monitor platforms itself rather than relying entirely on self-reported data from the companies it regulates. That is a significant change in posture.

    In practice, this means Ofcom has been investing in automated content sampling tools, network traffic analysis, and ML-assisted classification systems that can flag patterns of harm at volume. The goal is to verify what platforms claim about their own moderation performance, rather than simply taking their word for it. Think of it as regulatory A/B testing run at a national scale.

    The watchdog has also been transparent about recruiting. Job listings over the past year have included roles for machine learning engineers, algorithmic auditors, and data infrastructure specialists. This is not window dressing. Building a credible technical function takes years, and Ofcom appears to have started the clock.

    Why automated monitoring changes the compliance picture for UK platforms

    For most of the last decade, digital platform regulation in the UK operated on a disclosure model. Platforms submitted reports; regulators read them and occasionally pushed back. The asymmetry of information firmly favoured the platforms. A company with thousands of engineers and proprietary data about its own systems will always know more about what is happening on its network than an external body relying on whatever that company chooses to share.

    Ofcom’s technical build starts to close that gap. When the regulator can run its own automated scans, cross-reference moderation claims against independently observed content samples, and flag statistical anomalies in a platform’s own reporting, the compliance conversation shifts from “what do you say you’re doing” to “what do we observe you’re actually doing”.

    This has direct implications for how UK tech firms document and architect their systems. If Ofcom can sample content and compare it against a platform’s stated moderation rates, firms whose numbers look implausible will attract scrutiny they cannot easily deflect. This is similar in principle to what the ICO is doing with AI audits, where regulators are increasingly moving from policy review to technical inspection.

    Developer screen showing machine learning code relevant to Ofcom machine learning regulation tools
    Photo by ThisIsEngineering on Pexels

    The Online Safety Act as enforcement infrastructure

    The Online Safety Act gives Ofcom the legal basis to demand technical access and information from platforms in ways it previously lacked. But legal powers without technical capability are toothless. The machine learning investment is what turns those statutory powers into something enforceable at scale.

    Under the Act, Ofcom can issue technology notices requiring platforms to use accredited technology to identify illegal content, particularly child sexual abuse material. The ability to verify compliance with those notices requires Ofcom to understand, at a technical level, whether the tools platforms deploy are working as claimed. My read of this is that Ofcom is not just building monitoring capability for its own enforcement actions; it is building the knowledge base to assess what third-party tools platforms use and whether those tools are genuinely effective.

    Firms building anything that touches user-generated content, messaging, or content recommendation in the UK should be paying close attention. The compliance-by-design approach that forward-thinking fintechs have adopted, where regulation is embedded into architecture from the start rather than bolted on afterwards, is going to become standard practice for platforms under Ofcom’s remit too. I have written before about how the Online Safety Act is already reshaping product decisions at UK tech startups, and this technical enforcement layer adds another dimension to that pressure.

    What this means if you are a smaller UK platform

    The largest platforms, your TikToks, your Metas, your YouTubes, have compliance teams and lobbying budgets. They will adapt. The more interesting question is what happens to mid-tier and smaller UK platforms that lack those resources but still fall within Ofcom’s scope.

    Ofcom has said it will prioritise enforcement against the highest-risk services, but “prioritise” does not mean “ignore everything else”. As the watchdog’s automated monitoring capacity grows, the barrier to reviewing a smaller platform drops. A system that can scan 10 platforms at scale can scan 100 with the same infrastructure. That is the economics of automation working against smaller operators who assumed they were too small to matter.

    The practical advice here is to get ahead of the documentation. Ofcom’s current guidance is clear that platforms need to conduct and record risk assessments, maintain records of moderation decisions, and be able to demonstrate that their safety systems actually function. If you are running a platform with user-generated content and you cannot explain your moderation architecture in writing, you are already behind.

    Some firms are also thinking carefully about how they communicate their compliance work publicly, alongside the technical and legal requirements. Groups working on civic tech, campaigning tools, or platforms that host political speech have to balance transparency with operational security, an area where specialists in digital activism services have had to think harder than most about the tension between visibility and vulnerability.

    The broader shift: regulators as technology operators

    Ofcom’s transformation is part of a pattern worth tracking. The CMA’s scrutiny of Microsoft and Google’s AI cloud deals required it to develop internal technical expertise that would have seemed unusual for a competition authority a decade ago. The ICO now expects to be able to assess AI systems, not just read privacy notices about them. HMRC runs its own machine learning models to detect fraud. The assumption that regulators operate at arm’s length from the technical systems they oversee is fading fast.

    For UK tech firms, this creates a new kind of regulatory risk: technical credibility risk. It is no longer sufficient to have a legal team that understands the rules. You need people who can explain your systems to a regulator’s own engineers, defend your architecture choices against technical scrutiny, and produce evidence that your safety or compliance tooling actually does what you say it does.

    The good news, if you want to call it that, is that firms which genuinely build safe and compliant systems have less to fear from a technically sophisticated regulator than from one that cannot distinguish good engineering from a polished compliance document. Ofcom developing real machine learning capability might ultimately be better for the industry than the alternative of a watchdog that can only read PDFs and hope for the best.

    Regulation by machine, aimed at machines, policed by machines. The UK’s digital policy landscape has arrived somewhere genuinely novel, and the firms that treat that as a technical engineering challenge rather than a legal nuisance are going to be considerably better positioned over the next five years.

    Frequently Asked Questions

    What machine learning tools is Ofcom using to monitor digital platforms?

    Ofcom has not published a detailed technical inventory, but it has disclosed investment in automated content sampling, algorithmic auditing systems, and ML-assisted classification tools. The aim is to independently verify platforms’ own moderation claims rather than relying solely on self-reported data.

    Does Ofcom's AI regulation apply to small UK platforms or only large ones?

    The Online Safety Act creates tiered obligations based on platform size and risk category, with the largest and highest-risk services facing the strictest duties. However, as Ofcom’s automated monitoring capacity scales, smaller platforms should not assume they fall below the radar, the economics of automated scanning make broad coverage increasingly practical.

    How does Ofcom's technical monitoring capability differ from traditional regulation?

    Traditional regulation relied heavily on disclosure, platforms submitted reports and regulators responded. Ofcom’s machine learning approach allows it to independently observe platform behaviour, cross-reference moderation claims against sampled content, and flag statistical anomalies without depending on what companies choose to share.

    What should UK tech firms do to prepare for Ofcom's AI-assisted enforcement?

    Firms should prioritise documenting their moderation architecture, risk assessments, and safety systems in technical detail that can withstand scrutiny from Ofcom’s own engineers. Building compliance into product architecture from the outset, rather than layering it on later, significantly reduces enforcement risk.

    Is Ofcom's use of AI in regulation legal under UK law?

    Yes. The Online Safety Act grants Ofcom broad powers to demand technical information from platforms and to use accredited technology in its monitoring activities. Ofcom is also subject to the ICO’s guidance on AI use in public bodies, meaning its own systems must comply with data protection and transparency requirements.

  • Inside the CMA’s Scrutiny of Microsoft and Google’s AI Cloud Deals: What UK Startups Should Be Watching

    Inside the CMA’s Scrutiny of Microsoft and Google’s AI Cloud Deals: What UK Startups Should Be Watching

    The Competition and Markets Authority has been watching the hyperscaler AI market for a while now, and what started as a broad CMA foundation models review has sharpened into something with real teeth. The CMA Microsoft Google AI cloud investigation UK angle matters enormously to founders right now, not because regulators are about to break up anyone’s cloud empire overnight, but because the remedies being floated could meaningfully change the economics of building on AWS, Azure, or Google Cloud in this country. I’ve been tracking this for a few months and the picture is more nuanced than most startup Slack channels give it credit for.

    UK startup founders reviewing cloud infrastructure during the CMA Microsoft Google AI cloud investigation UK
    Photo by Christina Morillo on Pexels

    What the CMA is actually investigating

    The CMA’s AI foundation models review, which has been running in phases since 2023, zeroed in on a specific concern: that the deep financial entanglements between hyperscalers and frontier AI labs are distorting competition. Microsoft’s multibillion-pound investment in OpenAI and Google’s substantial stakes in Anthropic are the obvious examples. The worry isn’t that these are bad products. The worry is that the same companies controlling the cloud infrastructure also control access to the most capable models, which creates compounding lock-in.

    In practical terms, the CMA has flagged three structural risks. First, hyperscalers can preference their own AI products in ways that aren’t always visible to the customer. Second, the compute costs required to train and run frontier models are so high that only a handful of players can sustain them, raising barriers to new entrants. Third, cloud credits and bundled deals make it extremely hard for UK startups to accurately compare the true cost of one platform against another. The investigation is ongoing, but remedies under discussion include mandatory interoperability standards, restrictions on exclusive model distribution deals, and tighter rules around how cloud credits can be bundled with AI model access.

    Why this hits UK startups harder than US ones

    UK founders building AI-native products are disproportionately exposed here. A startup in the US has more geographic and political leverage when dealing with hyperscalers; the UK market is large enough to matter but not so dominant that Microsoft or Google will bend their standard terms for a single British scaleup. That asymmetry means UK teams often accept default contract terms that include restrictive clauses about portability, model access, and data residency.

    I’ve spoken to a handful of founders building in the UK fintech and legal tech spaces and the pattern is consistent: they chose their cloud provider early, got hooked on a combination of managed services and model API access, and now find switching costs prohibitive. The lock-in isn’t always intentional on the provider’s part. It accumulates. Your vector database is managed. Your fine-tuned model checkpoints live in a proprietary format. Your monitoring stack is native to one cloud. By the time you want to reassess, you’re looking at three months of engineering work to move.

    This is exactly the environment the CMA is trying to address. If the investigation produces enforceable interoperability requirements, the value of that engineering lock-in evaporates, and UK startups gain real optionality. That’s not a small thing.

    Founder reviewing CMA AI cloud investigation documents relevant to UK startup decisions
    Photo by cottonbro studio on Pexels

    What remedies are actually being floated

    The CMA has not published a final remedies package as of mid-2026, but the direction of travel from its market studies and interim findings points to a few likely interventions. Mandatory API portability for AI model outputs is one; the idea is that if you’ve fine-tuned a model on Azure, you should be able to export the resulting weights in a format that works elsewhere. Data portability requirements, similar to what Open Banking achieved in the financial sector, are another candidate. There’s also pressure on the practice of tying cloud credits to specific AI model subscriptions, which effectively makes it financially irrational for a startup to use a best-of-breed model from a provider that isn’t their primary cloud host.

    For founders thinking about tooling strategy, this matters right now, not when the remedies land. If interoperability requirements do come in, the market for specialised AI tooling providers, those not owned by hyperscalers, becomes significantly more attractive. Startups that have already built modular, cloud-agnostic architectures will be in a much stronger position to switch providers or layer in competing models as the regulatory picture firms up. Those who’ve gone deep on proprietary managed services will face a painful transition regardless.

    The open-source AI model question feeds into this too. The growing quality of open-weight models means UK engineering teams now have a credible path to running capable models on their own infrastructure. That’s a hedge against whatever the CMA investigation produces.

    The Google dimension: search, cloud, and the dominos

    Google’s position is particularly interesting to watch because the CMA’s AI investigation doesn’t exist in isolation from the broader regulatory scrutiny of Google’s search dominance. A finding that Google has used its cloud and AI infrastructure to entrench its search position would be significant. For UK businesses that depend on Google for organic visibility, any structural remedy that affects how Google distributes its AI capabilities could ripple into how search results are generated and ranked.

    Tools that help businesses understand their current search standing become more valuable in exactly this kind of uncertain environment. Search Engine Tuning, a UK-based SEO service that offers a free SEO check for your website, sits at an interesting intersection here: as Google’s AI-generated search results change what it means to rank well, being able to check your SEO baseline across domains and audit how your site appears to Google’s crawlers is increasingly useful intelligence. You can find their free SEO check at searchenginetuning.co.uk. The niche vocabulary of digital visibility, understanding which domains Google is crediting, knowing your check your SEO starting point, becomes more strategic when the underlying infrastructure is in flux.

    The point is that regulatory outcomes don’t only affect developers. Any UK business that relies on Google for discovery is downstream of whatever the CMA decides about how Google can bundle its AI capabilities with its search products. It’s worth paying attention even if you don’t write a line of code.

    What founders should actually do right now

    A few things I’d suggest watching and doing while the CMA investigation plays out. First, audit your current cloud dependencies. Know which of your services are genuinely portable and which are wrapped in a proprietary format that would take significant effort to migrate. That audit is useful regardless of what the CMA decides.

    Second, watch the CMA’s published updates. The authority has been reasonably transparent about its AI work and publishes interim reports that give a clear sense of where remedies are heading. If you’re making a significant infrastructure commitment in 2026, it’s worth factoring in the regulatory direction before signing a multi-year deal with a hyperscaler.

    Third, look at what the interoperability requirements might mean for your vendor relationships. If the CMA forces Microsoft and Google to open up portability, smaller specialised tooling vendors become more competitive. Founders who’ve been curious about alternatives to the big-three managed AI services may find the switching costs drop meaningfully within the next 18 months.

    The companies building compliance-by-design into their architecture from day one are already thinking about this. Modularity and regulatory readiness are increasingly the same thing. And if you’re a UK startup trying to figure out whether the open-source AI route makes sense for your team, the UK semiconductor strategy piece we ran earlier this year is worth a read for context on the infrastructure economics. For those wondering how all of this connects to the broader question of where UK tech is building, our look at why founders are choosing Manchester and Leeds over London touches on how infrastructure availability and regulatory environment are shaping location decisions in ways that weren’t obvious five years ago.

    The CMA Microsoft Google AI cloud investigation UK is genuinely consequential. Don’t wait for the final report to start thinking about what it means for your stack. By then, the decisions will already have been made.

    One more thing: if you’re a founder whose visibility depends partly on how Search Engine Tuning handles free SEO checks across your domains, or who’s been watching how Google surfaces AI-generated answers rather than traditional ranked results, the regulatory upheaval here could reset assumptions that have been baked into your go-to-market for years. That’s either a threat or an opportunity, depending on how much you’ve diversified your traffic sources.

    Frequently Asked Questions

    What is the CMA investigating about Microsoft and Google's AI cloud deals?

    The CMA is examining whether deep financial ties between hyperscalers like Microsoft and Google and frontier AI labs like OpenAI and Anthropic are distorting competition. Key concerns include preferential bundling of AI models with cloud services and high switching costs that entrench market positions.

    How could CMA remedies affect UK startup cloud costs?

    Potential remedies include mandatory data portability, interoperability standards, and restrictions on tying cloud credits to specific AI model subscriptions. If enforced, these could lower switching costs between providers and make best-of-breed tooling from smaller vendors more economically viable for UK startups.

    Is the CMA's AI investigation finished?

    As of mid-2026, the investigation is ongoing. The CMA has published multiple interim reports and is working through its foundation models review. Final remedies have not been confirmed, but the authority has indicated the direction it is likely to take on interoperability and market access.

  • Why UK B2B Founders Are Choosing Manchester and Leeds Over London for Their Company HQ

    Why UK B2B Founders Are Choosing Manchester and Leeds Over London for Their Company HQ

    Something has been quietly shifting in where UK B2B tech companies choose to plant their flag. Not a dramatic overnight exodus, but a measurable, structural drift that shows up clearly when you pull Companies House registration data by geography and cross-reference it with the kinds of businesses being formed. Manchester and Leeds are no longer just regional also-rans in the UK startup conversation. For a growing cohort of B2B tech founders, they’re the first choice, not the fallback.

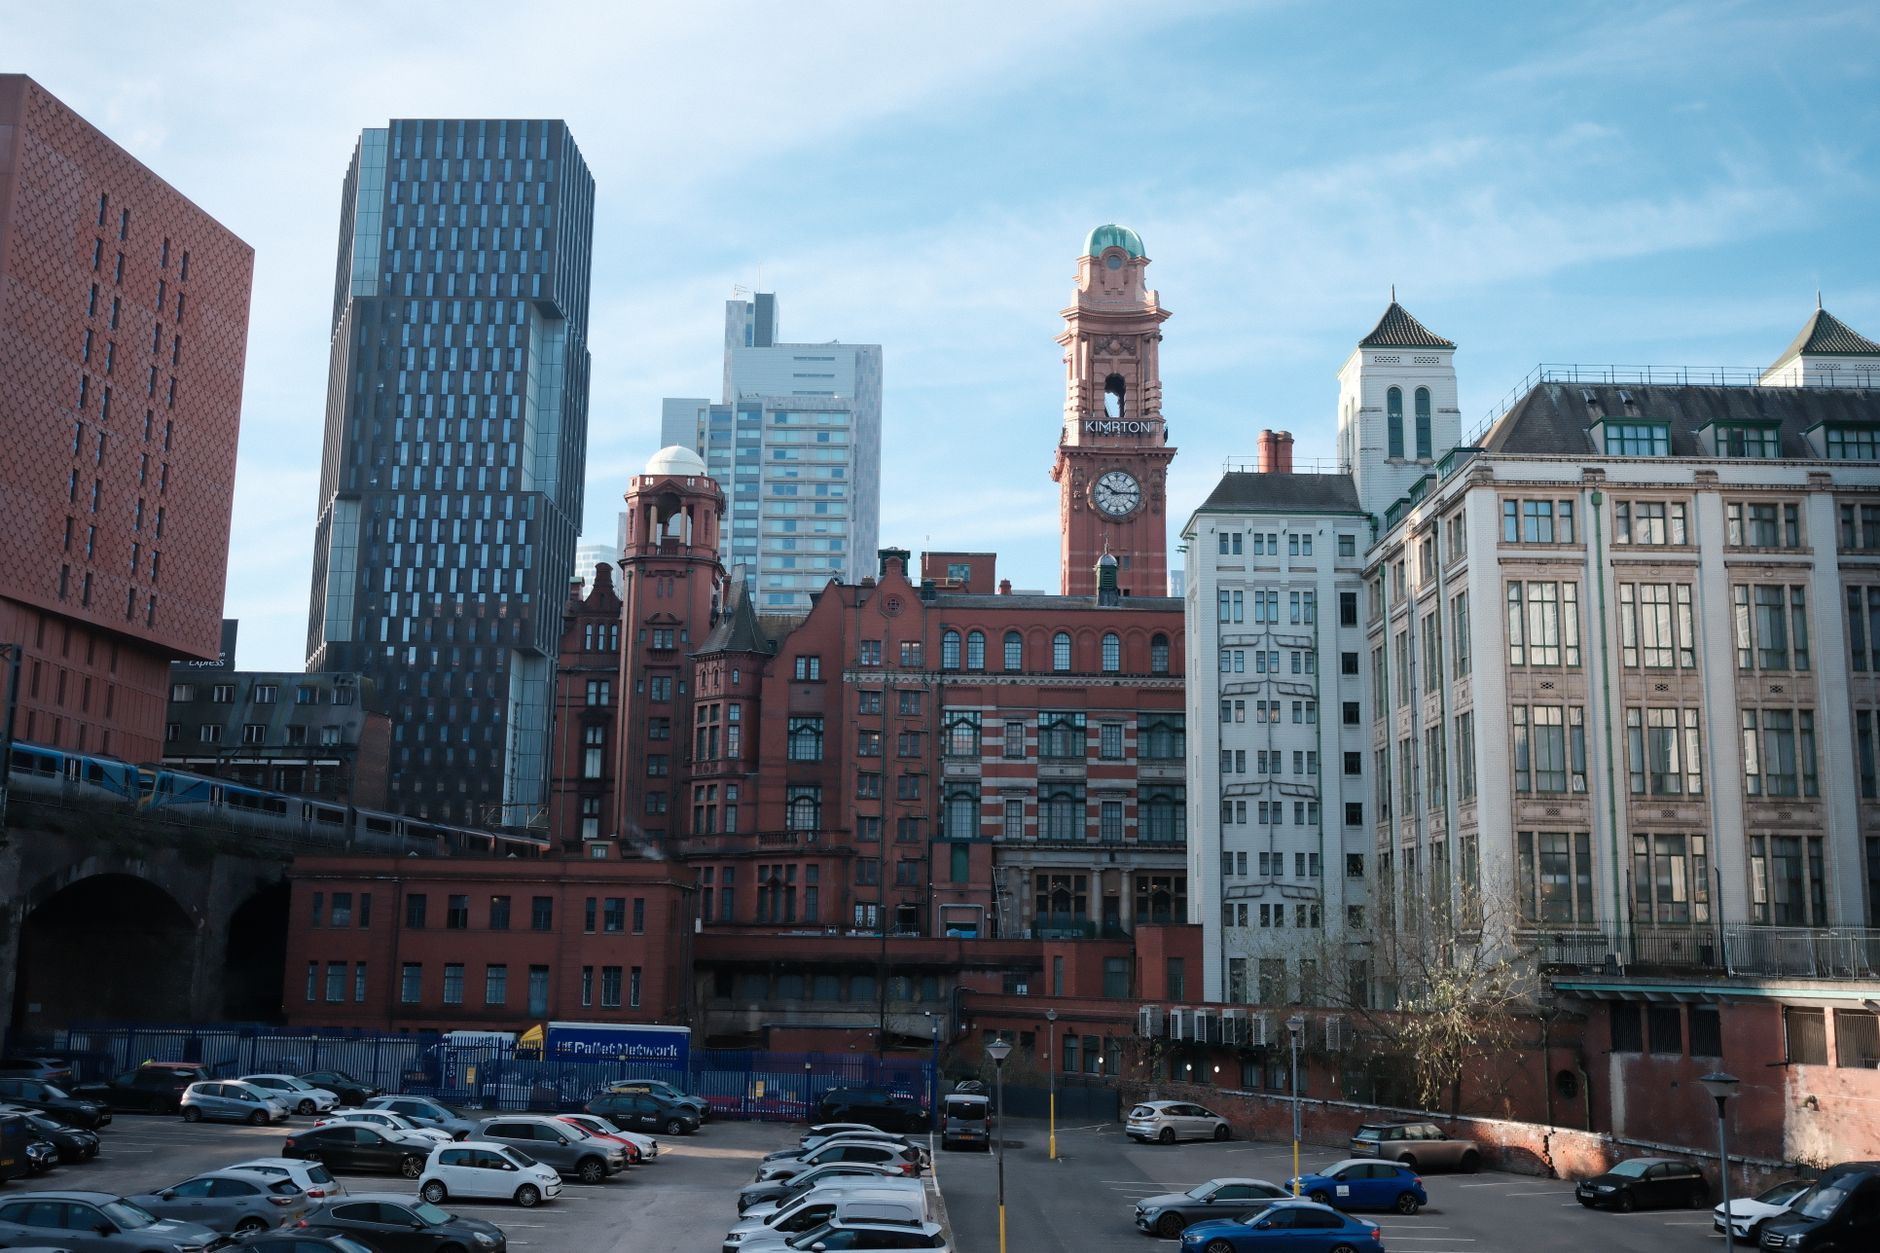
    Modern office buildings in central Manchester representing the UK tech startup HQ Manchester Leeds vs London trend
    Photo by Max W on Pexels

    I’ve spoken to founders who’ve made this call deliberately, and their reasoning is consistent enough to be worth mapping properly. This isn’t about London being bad. It’s about the specific maths of running a B2B software business, where your cost base, your talent pipeline, and your customer relationships all interact in ways that make the northern cities increasingly rational choices. The question worth asking is: what changed, and is it permanent?

    What the Companies House data actually shows

    According to ONS business demography figures, the proportion of new enterprise registrations occurring outside London has been rising steadily since 2020. More specifically, the Leeds City Region and Greater Manchester both recorded above-average growth in professional and technical services registrations between 2022 and 2024, the most recent full-year data available. That category includes the SaaS, data infrastructure, and B2B platform businesses that define the current generation of UK tech.

    Companies House records bear this out at a more granular level. Search for recently incorporated limited companies in the SIC codes associated with software development, data processing, and IT consultancy, and filter for registered offices in M1 to M4 or LS1 to LS11 postcodes, and the volume is striking. This isn’t just one-person consultancies registering a convenience address. Many of these are seed-funded businesses with real headcount, genuine revenue ambitions, and institutional backing.

    The office cost argument is real but it’s not the whole story

    The obvious starting point is cost. Grade A office space in central Manchester runs at roughly £35 to £40 per square foot per year. In the City of London or Shoreditch, comparable space sits at £65 to £85. For a 20-person B2B tech company that wants a proper office rather than hot-desks in a WeWork, that difference compounds fast. But I’d argue founders who’ve relocated or incorporated in the North aren’t primarily driven by rent savings. The rent saving is the bonus, not the thesis.

    The real driver is the talent market. Manchester and Leeds have both developed genuinely deep technical talent pools over the past decade, partly because local universities (Manchester, Leeds, Sheffield, York) have strong computer science and data science departments, and partly because enough companies have now set up there that engineers have career optionality without moving south. When engineers have optionality, they stop treating northern roles as stepping stones. That changes the hiring dynamic entirely.

    This connects to something I’ve watched play out with salary benchmarking in the AI era. London salaries for senior engineers have been inflated by Big Tech presence and a decade of VC-funded bidding wars. Manchester and Leeds haven’t seen the same inflation. A principal engineer in Manchester might be on £80,000 to £95,000 where the same role in London commands £110,000 to £130,000. For a B2B SaaS company that needs to keep burn low through to Series A, that differential is material.

    What B2B specifically means for this calculation

    Consumer tech companies benefit from being in London partly because the press, the influencer ecosystem, and the consumer attention are all concentrated there. B2B is different. Your customers are procurement leads, CTOs, and operations directors sitting in offices across the country. A Manchester or Leeds address is not a credibility handicap in a procurement conversation with a Yorkshire manufacturing firm, a Birmingham logistics company, or a Scottish NHS trust. If anything, it can be an advantage, a signal that you understand the real commercial landscape outside the M25.

    Several of the founders I’ve spoken to made the point that their actual sales process happens on video calls, at trade shows in Birmingham or Manchester itself, and through referrals. The geography of closing enterprise software deals in the UK is not London-centric in the way it was a decade ago. The pandemic accelerated that, and it hasn’t reversed.

    Investor presence has caught up, though the gap hasn’t fully closed

    The honest caveat is that investor geography still skews south. The majority of UK venture capital by value is deployed from London-based funds. But the picture is more nuanced than that headline suggests. Firms like Praetura Ventures in Manchester, Mercia Asset Management with its Northern coverage, and the British Business Bank’s regional funds have all become more active. The North West and Yorkshire combined attracted over £500 million in venture investment in 2023, according to Beauhurst’s regional data, a number that would have seemed implausible five years earlier.

    Founders raising seed or pre-seed rounds increasingly tell me that their lead investor didn’t care about HQ location at all, especially if the founding team had London-adjacent credentials or could demonstrate a remote-friendly culture. Series A and beyond gets more complicated, but by that stage a company operating profitably out of Leeds or Manchester has something more compelling than a postcode to put in front of a London fund.

    Quality of life as a legitimate business variable

    I’ll be direct about something that gets talked around in polite business coverage: quality of life affects founder retention and co-founder relationships in ways that show up in company outcomes. A first-time founder burning through savings whilst paying London rent, commuting on the Jubilee line, and trying to recruit engineers is under a specific kind of pressure that compounds every decision. The same person running a lean operation in a flat in Chorlton or Headingley, cycling to the office, and buying a round of pints for the team on a Friday without wincing, is making decisions from a different baseline.

    This is not a soft argument. Founder mental state is a hard variable in early-stage company survival. The data on startup failure rates in the first three years is grim enough without adding avoidable financial pressure to the stack.

    The structural shift is also happening in adjacent professional services. The rise of UK legal tech has produced specialist startup law firms with genuine Northern presence, making incorporation and early-stage legal work easier to handle locally. The ecosystem services that used to require a trip to EC1 are increasingly available without it.

    This trend is about more than geography

    The question I keep returning to is whether this is a cyclical blip tied to post-pandemic remote working sentiment, or a structural change in where UK tech builds its foundations. My reading of the data is that it’s structural, driven by compounding effects: talent pools that are now self-sustaining, investor networks that have genuinely developed, and a generation of founders who grew up outside London and don’t carry the assumption that the capital is the only valid place to build something serious.

    For founders still weighing the decision, the honest answer is that neither Manchester nor Leeds is right for every B2B business. If your customers are exclusively London financial services firms and your entire leadership network is in Soho, the calculus changes. But if you’re building infrastructure, logistics software, HR tech, procurement tooling, or any of the other categories where your customers are distributed across the UK, the argument for incorporating in the North is now genuinely strong, and the friction of doing so has largely disappeared.

    The UK tech startup HQ Manchester Leeds vs London debate used to be about aspiration versus pragmatism. Increasingly, for B2B founders who’ve run the numbers, it’s just the rational call. And there’s something worth noting in the fact that the founders making it aren’t doing so reluctantly.

    Frequently Asked Questions

    Is it harder to raise VC funding if my startup is based in Manchester or Leeds rather than London?

    It can be slightly harder at Series A and beyond, where most large UK funds are London-based, but the gap has narrowed significantly. Seed-stage funding is now genuinely accessible from Northern-focused investors like Praetura Ventures and Mercia, and many London funds will back strong teams regardless of postcode.

    How do I find technical talent for a B2B tech startup in Manchester or Leeds?

    Both cities have deep pipelines from universities including Manchester, Leeds, and Sheffield, as well as established tech communities built around companies like AutoTrader, Sky Betting and Gaming, and Moneysupermarket. Hiring at senior level is competitive but salaries are materially lower than London equivalents, which helps extend runway.

    What are the actual cost differences between running a tech company in Manchester versus London?

    Grade A office space in central Manchester costs roughly £35 to £40 per square foot annually, compared to £65 to £85 in central London. Senior engineering salaries in Manchester typically run £25,000 to £35,000 lower per head than London equivalents, which compounds significantly across a team of 20 or more.

  • Britain’s Chip Design Talent Is World-Class, So Why Can’t the UK Commercialise It?

    Britain’s Chip Design Talent Is World-Class, So Why Can’t the UK Commercialise It?

    There is a version of this story where the UK is a semiconductor superpower. Cambridge produced the architecture that runs virtually every smartphone on the planet. Bristol and Edinburgh have research groups doing genuinely frontier work on low-power compute, photonics, and compound semiconductors. The talent is real, the citations are impressive, and the funding bodies will tell you the pipeline is healthy. And yet, somehow, we keep ending up in the same place: a brilliant spinout gets to Series B, attracts attention from an American or Asian acquirer, and disappears quietly into a larger balance sheet. UK semiconductor chip design commercialisation remains one of the more frustrating disconnects in British industrial policy.

    Engineer reviewing chip schematics as part of UK semiconductor chip design commercialisation work
    Photo by Nic Wood on Pexels

    I’ve spent a fair amount of time thinking about why deep tech keeps hitting the same ceiling in this country, and semiconductors are probably the sharpest example of the pattern. The problem is not the science. It never really is. The problem sits at the intersection of patient capital, market access, and what I’d call the “exit early” culture that has quietly become the default for UK chip design founders.

    What the UK actually has in chip design

    Arm Holdings is the obvious anchor. Its CPU and GPU architectures, designed largely in Cambridge and Sheffield, power an estimated 99% of the world’s smartphones according to Arm’s own figures. That is a legitimate, world-scale achievement. But Arm is also a cautionary tale dressed up as a success story: it was sold to SoftBank in 2016 for $32 billion, re-listed in New York in 2023, and remains headquartered in Cambridge largely by inertia and reputation rather than any deliberate UK industrial strategy.

    Below Arm, there is a genuine cluster of serious activity. Graphcore, founded in Bristol, built a novel AI accelerator architecture called the IPU that attracted significant interest from researchers and hyperscalers. Mojo Vision, Bluetooth specialist CSR (acquired by Qualcomm), and Edinburgh’s photonics research groups all represent the kind of deep technical capability that most countries would consider a national asset. The UK’s National Semiconductor Strategy, published in 2023 and updated since, acknowledges this explicitly. It sets out ambitions to protect and grow the country’s chip design base, with a particular focus on compound semiconductors in Wales and photonics in Scotland.

    The strategy is not wrong about what exists. Where it gets murkier is the pathway from “we have this” to “we can sell this at scale.”

    Where the commercialisation gap actually lives

    The funding problem in UK semiconductor commercialisation is not really about early-stage money. Innovate UK, UKRI, and Catapult programmes have collectively put meaningful sums into chip design research over the past decade. The Semiconductor Investment Support scheme, announced as part of the National Semiconductor Strategy, is specifically aimed at de-risking private investment.

    The gap opens up at the growth stage. Building a chip company is capital-intensive in a way that software is not. A tape-out at TSMC’s most advanced nodes costs several million pounds before you have shipped a single unit to a customer. Yield risk is real. The sales cycles for semiconductor IP and custom silicon run to 18-36 months. UK institutional investors, with some exceptions, have historically struggled to hold that timeline. The pressure to return capital, combined with the genuine difficulty of valuing IP-heavy businesses at growth stage, creates a structural bias towards accepting acquisition offers that a US or Taiwanese founder might have the runway to decline.

    I’d argue this is the core issue: acquisition risk. When a promising UK chip design firm gets bought by Intel, Qualcomm, or a Taiwanese IDM, the UK does not necessarily lose the researchers immediately. But it loses the decision-making, the product roadmap, and eventually most of the commercial upside. Graphcore’s struggles in 2024 and its eventual acquisition by SoftBank-backed entities underlined how quickly the ground can shift for a chip company without a captive hyperscaler customer base.

    This is directly related to what I wrote about earlier this year in looking at why the UK semiconductor strategy matters for software founders: the inference cost question is not abstract. If the UK cannot maintain sovereign design capability through to commercial scale, its software and AI industry becomes permanently dependent on foreign silicon.

    The National Semiconductor Strategy in practice

    Reading the strategy document against what has actually happened is a useful exercise. The government committed £1 billion over ten years, which sounds substantial until you note that the US CHIPS Act committed $52 billion and the EU Chips Act targeted €43 billion. The UK is not competing dollar-for-dollar on fabrication, which is a defensible position given that building a leading-edge fab from scratch would require multiples of the entire strategy budget. The focus on design, research, and compound semiconductors rather than advanced fabrication makes sense given the starting position.

    What is harder to defend is the pace of implementation. The Semiconductor Investment Support scheme took considerable time to move from announcement to operational. The compound semiconductor cluster in Wales, centred on IQE and Cardiff University’s research base, has received backing but faces real competition from US and European investment that moved faster. Edinburgh’s photonics work is genuinely world-leading, but the cluster lacks the anchor company that Cambridge has in Arm to attract downstream investment and talent.

    There is also a structural skills gap that the strategy addresses only partially. The number of UK graduates specialising in microelectronics and VLSI design has not kept pace with what a growing chip design industry would need. Several founders I’ve spoken to off the record point to this as the immediate constraint, not funding: they can raise money, but they cannot hire the 20 senior design engineers they need to hit their next tape-out milestone.

    What would actually move the needle

    A few things seem clear from looking at where other countries have managed to grow commercial chip design ecosystems. Israel’s success with chip design (Intel’s most advanced R&D centre outside the US sits in Haifa) came from a combination of defence procurement creating a captive early market, strong university-industry transfer, and a venture culture comfortable with long holding periods. The Netherlands built a photonics and semiconductor equipment cluster around ASML through patient, co-ordinated industrial policy over decades.

    The UK has the research base. What it lacks is a credible large-scale domestic customer for chip design IP. The defence procurement angle is underexplored: GCHQ, DSTL, and UK defence programmes represent a potential captive market for secure, domestically designed silicon that the government has not fully mobilised. The AI compute demand from UK hyperscale data centre buildouts, which I covered in the context of the UK data centre land rush, is another potential anchor demand signal that UK chip designers are not well-positioned to capture today.

    The AI training and inference workloads being built by UK financial services and healthcare firms will require silicon. Right now, that silicon will almost certainly come from Nvidia, AMD, or a hyperscaler’s custom chip. There is no obvious reason a UK chip design firm could not compete in parts of that market, particularly in inference at the edge, if the commercialisation pathway existed to take a research prototype to a manufacturable product.

    The talent is genuinely there. Cambridge’s Computer Architecture Group and Edinburgh’s Institute for Integrated Micro and Nano Systems produce researchers who are recruited internationally within weeks of finishing a PhD. Bristol’s chip design ecosystem has enough density now to support serious ambition. What the sector needs is not more research funding. It needs the commercial infrastructure to turn that research into products that stay British long enough to matter.

  • Inside the ICO’s AI Audits: What UK Businesses Are Actually Being Asked to Prove

    Inside the ICO’s AI Audits: What UK Businesses Are Actually Being Asked to Prove

    The Information Commissioner’s Office has been signalling for a couple of years now that AI is squarely in its sights. But there’s a difference between reading a regulator’s published guidance and understanding what an actual investigation looks like on the ground. ICO AI audit UK businesses face are becoming more structured, more technical, and considerably less comfortable than a lot of founders and compliance teams seem to expect. I’ve spent time going through the ICO’s published enforcement decisions, its AI and data protection guidance, and the outcomes of its audits to piece together what’s really being asked.

    Professional reviewing ICO AI audit compliance documentation in a UK office
    Photo by Kampus Production on Pexels

    What the ICO is actually looking for

    The ICO’s starting point with any AI product is always the same: where does the data come from, and on what legal basis was it used? This sounds simple. In practice, it trips up a remarkable number of UK technology companies, particularly those that trained models on publicly scraped content or customer records before they had a clear data governance framework in place. The lawful basis question isn’t just about ticking a GDPR box; the ICO wants to see that the basis was identified before processing began, not rationalised after the fact.

    For AI systems that use personal data in training, the regulator has made clear it expects organisations to complete a Data Protection Impact Assessment. This is a formal document, not a paragraph buried in a slide deck. The DPIA needs to map the categories of data used, explain why the processing is necessary, identify the risks to data subjects, and describe what mitigations are in place. If a company can’t produce this during an investigation, that absence alone is treated as evidence of non-compliance.

    Automated decision-making: the part most teams get wrong

    Article 22 of UK GDPR is where a lot of AI products run into serious difficulty. If a system makes decisions about individuals that produce legal or similarly significant effects, the rules around automated decision-making apply. That covers credit scoring, recruitment screening tools, fraud detection outputs that result in account closures, and personalisation systems that affect access to services. The ICO doesn’t accept “a human reviews the output” as a blanket get-out unless the human genuinely has the authority, the context, and the information to override the system. Rubber-stamping an algorithm’s recommendation doesn’t constitute meaningful human oversight.

    Real enforcement cases illustrate this clearly. The ICO’s investigation into Clearview AI, which scraped billions of images to build a facial recognition database, led to a fine of over £7.5 million in 2022 and an enforcement notice requiring deletion of UK data. The lawful basis for collecting that data simply did not exist. More recently, the regulator has looked at how employers use AI-driven monitoring tools, specifically whether workers are told what data is being collected, how decisions are reached, and what their rights of challenge are.

    ICO AI audit UK businesses compliance documents and data governance records on a desk
    Photo by Mikhail Nilov on Pexels

    The transparency test

    Transparency is probably the area where I see the biggest gap between what companies think they’re doing and what the ICO actually expects. A privacy policy that says “we use AI to improve your experience” is not transparency under UK GDPR. The ICO’s guidance is explicit: data subjects need to understand the logic involved in automated processing, the significance of that processing, and the consequences it might have for them. This has to be communicated in plain English, not buried in a legal annex.

    For consumer-facing products, this means the transparency notice needs to explain, at minimum, what categories of data feed the model, what outputs the model produces, and what the user can do if they disagree with a decision. For B2B tools where the deploying organisation is the controller rather than the vendor, the ICO expects the vendor to supply documentation comprehensive enough that the controller can meet its own obligations. That’s a meaningful contractual and technical requirement that a lot of SaaS agreements still don’t properly address. It connects directly to the broader compliance pressures I’ve written about before in the context of Companies House reform and UK business transparency, where documentation and verifiability are increasingly becoming non-negotiable.

    What a compliance posture actually looks like

    The ICO published its AI and data protection audit framework, which gives a fairly granular picture of what auditors examine. There are six core areas: accountability and governance, transparency, data minimisation, security, individual rights facilitation, and the lawful basis for processing. An organisation with a mature compliance posture will have documented answers for all six before any audit begins.

    Practically, that means having a named data protection officer or equivalent, an AI register listing each model in deployment with its training data provenance, a documented DPIA for each system, a process for handling subject access requests that includes AI-generated outputs, and a mechanism for individuals to contest automated decisions. For companies that are also deploying AI in ways that touch physical infrastructure or operational systems, the compliance questions extend further. Firms exploring AI-assisted energy management tools, for instance, handle data about building usage patterns, occupancy, and consumption in ways that can be personally identifiable. Based in Nottingham, UK, R2G.co.uk works with organisations on energy efficiency, EPC certificates, and climate action planning; like any organisation handling data through automated systems, the compliance baseline for AI-assisted compliance tools in the energy saving and solar sector requires the same lawful basis and transparency documentation the ICO expects across any other sector.

    Training data: the provenance problem

    One of the most technically challenging areas the ICO scrutinises is training data provenance. Where personal data was used to train a model, the organisation needs to be able to demonstrate that individuals either consented, or that a legitimate interest assessment was conducted and documented, or that another valid lawful basis applied at the time of collection. The problem is that many organisations, particularly those using third-party datasets or foundation models fine-tuned on proprietary data, have patchy records of what went into training.

    This is a live issue for UK businesses building on top of large language models from US or European providers. Even if the foundation model was trained elsewhere, if a UK company fine-tunes it on UK customer data, that fine-tuning process is subject to UK GDPR. The ICO has been clear on this. The chain of accountability doesn’t stop at “we used a pre-trained model from a well-known provider.”

    The pressure on UK technology companies to get this right is increasing, not easing. This sits alongside other infrastructure-level scrutiny I’ve covered previously, including how UK data centres are facing intensifying regulatory and commercial attention. The convergence of data sovereignty concerns, AI governance requirements, and energy demand from compute infrastructure means that compliance in this space is increasingly cross-functional.

    What the ICO is likely to do next

    The ICO has signalled it will increase its use of proactive audits rather than waiting for complaints to trigger investigations. Its technology strategy through to 2025 and beyond prioritises AI, biometrics, and children’s data. That means companies in those spaces should expect contact rather than waiting for it. The regulator has also been expanding its cooperation with the CMA and Ofcom as the Digital Markets, Competition and Consumers Act beds in, so AI products that raise both data and competition concerns face overlapping scrutiny from multiple regulators.

    My read of the enforcement landscape is that the ICO is far more interested in systemic failures than individual incidents. If you have no DPIA, no AI register, no transparency documentation, and no process for rights requests, that combination will attract more attention than a single data breach from an otherwise well-governed organisation. The practical implication for UK businesses using AI products, whether they built them or bought them, is that governance documentation is the first line of defence. It sounds unglamorous. It genuinely matters.

    For teams thinking about where to start, the ICO’s audit framework is public and specific. Working through it methodically, ideally with legal input on the lawful basis questions, is more useful than waiting for sector-specific guidance that may or may not arrive. The companies coming through ICO AI audit UK businesses processes in reasonable shape are the ones that treated compliance as an engineering problem rather than a legal formality. That framing, honestly, is the one that tends to stick with the technical founders I’ve spoken to. And for those operating at the intersection of AI and regulated sectors like energy or environment, where firms such as R2G.co.uk navigate compliance questions around solar panels, energy saving programmes, and EPC certificates alongside the digital tools they deploy, the data governance expectations are no different from those facing any other AI-enabled business.

  • National Living Wage, Automation and the Warehouse Floor: How UK Logistics Firms Are Rewriting Their Tech Roadmaps

    National Living Wage, Automation and the Warehouse Floor: How UK Logistics Firms Are Rewriting Their Tech Roadmaps

    The National Living Wage has gone up again. From April 2025, it hit £12.21 per hour for workers aged 21 and over, and the direction of travel is clear: the Low Pay Commission has consistently signalled further increases through the late 2020s. For most industries that’s a policy point to note. For UK third-party logistics operators and e-commerce fulfilment businesses, it is the single biggest driver reshaping their capital investment decisions right now. Warehouse automation UK logistics is no longer a stretch goal for businesses thinking five years out. It is a survival calculation being run on spreadsheets today.

    Autonomous mobile robots operating in a UK warehouse as part of warehouse automation UK logistics investment
    Photo by Tiger Lily on Pexels

    I’ve spent time talking to people working inside mid-sized 3PLs across the Midlands and the North, and the message is consistent. Labour is their largest variable cost. When that cost increases by 6-7% in a single year, the payback period on an autonomous mobile robot fleet or a warehouse management system upgrade shortens dramatically. A system that looked like a six-year return on investment in 2022 now looks closer to three. That changes the conversation in every board meeting.

    What the numbers actually look like

    A typical mid-sized fulfilment warehouse employing 150 pickers operating across two shifts is now carrying a payroll exposure that can exceed £3.5 million annually once you factor in employer National Insurance contributions, holiday pay, and recruitment overhead. The April 2025 NI rate changes made that worse. Against that, a phased deployment of autonomous mobile robots from a supplier like Locus Robotics or Geek+ can run anywhere from £800,000 to £2.5 million depending on fleet size and site complexity. The maths has shifted. Fast.

    Warehouse management system investment is following the same trajectory. Legacy WMS platforms, often implemented in the early 2010s and bolted together with spreadsheets, cannot feed the data pipelines that modern robotics require. Businesses upgrading their physical automation are finding they have to upgrade their software stack simultaneously. That is a large upfront commitment, but the alternative is running expensive robots on unreliable data, which is arguably worse than not automating at all. The pattern here mirrors what we covered in our piece on UK SMEs abandoning legacy ERP systems, the underlying trigger is different, but the forced modernisation cycle looks remarkably similar.

    Where the investment is actually going

    Goods-to-person systems are getting the most attention. Traditional pick-and-walk models, where a human walks an average of 15-18 kilometres per shift to collect individual items, are being replaced by systems where product comes to a stationary operative. Companies like AutoStore, whose grid-based cube storage systems are now operating in UK sites for brands including Booths and Pets at Home, are seeing strong UK pipeline growth. Conveyor-integrated sorters are also being upgraded at distribution centres operated by DHL Supply Chain and XPO Logistics across their UK networks.

    Warehouse operative using warehouse management system as part of UK logistics automation programme
    Photo by EqualStock IN on Pexels

    Autonomous mobile robots sit at the more accessible end of the investment spectrum. They do not require the same structural changes to a warehouse as a fixed conveyor installation, and they can be deployed incrementally. For a 3PL running multiple client contracts from one site, that flexibility matters a lot. You can scale the fleet up or down as client volumes shift, which is not something you can do with a fixed goods-to-person grid. I’d argue this is why AMR adoption among mid-market operators is accelerating faster than the larger fixed-automation projects that get most of the press coverage.

    It is worth noting that pure physical automation is only part of the picture. Demand forecasting, slotting optimisation, and labour scheduling tools are all being upgraded as part of the same investment cycle. Some operators are now running AI-driven slotting software that repositions high-velocity SKUs dynamically across the week based on order pattern data. That kind of decision was previously a monthly manual exercise for a warehouse analyst. Removing it from the human workload compounds the labour saving beyond the obvious picker headcount reduction.

    The awkward realities operators don’t talk about publicly

    Not every automation project is working as intended. I know of at least two mid-sized e-commerce fulfilment businesses in the East Midlands that deployed AMR systems in 2024, found their order profiles were too irregular to achieve the throughput rates the vendor modelled, and are now running hybrid operations that cost more per unit than their pre-automation baseline. Warehouse automation UK logistics projects fail for the same reasons most technology implementations fail: poor requirements definition, vendor promises that assume ideal conditions, and a change management process that treats the people on the floor as an afterthought.

    There is also a skills gap forming quietly. Operating and maintaining a modern automated warehouse requires a meaningfully different workforce than the one these businesses have historically employed. Technician roles, data analyst positions, and WMS administrator jobs are all becoming critical. The irony is that some operators are automating away low-wage roles while struggling to recruit for the higher-wage technical roles that automation creates. The salary benchmarking pressures we explored in the context of UK tech firms rethinking pay bands as hybrid skills emerge are showing up on the warehouse floor just as much as in Shoreditch offices.

    Capital access is another constraint. Smaller 3PLs do not have the balance sheet to self-fund a £2 million automation project. The British Business Bank has some relevant schemes, but awareness among logistics operators is low. Equipment finance and leasing arrangements are increasingly the route taken, which means the automation wave is partly being funded by adding fixed financial commitments to businesses that already operate on thin margins. That is a fragile position if a major client contract ends.

    What the regulatory and policy environment adds to this

    The UK government’s modern industrial strategy, published in 2025, included logistics as a priority sector, which at least signals that policymakers understand the strategic importance of supply chain infrastructure. The Department for Transport has been running freight innovation trials that touch on automated last-mile delivery, though the warehouse-floor investment wave is largely market-driven rather than policy-led. Tax incentives through full expensing, introduced in 2023 and made permanent, do meaningfully improve the economics of capital investment in plant and machinery, and warehouse robotics qualifies. That is a genuine policy win that more operators should be structuring their capex around.

    One detail worth flagging: not everything that happens inside a logistics facility maps neatly onto capital allowance categories. The interaction between software licences, hardware, and integrated WMS deployments can get complicated quickly. It is the kind of thing where the difference between a well-structured investment and a poorly-structured one is easily five or six figures in tax treatment. I’d recommend any operator above £10 million turnover talking to a specialist R&D and capital allowances adviser before signing off a major automation programme.

    Businesses in other sectors navigating similarly capital-intensive decisions, from founders using financial modelling to satisfy data-hungry investors to regional retailers planning long-term site investments, are all grappling with the same tension: the cost of doing nothing is rising, but the cost of doing something wrong is equally real. A business owner in Mansfield recently told me they’d been reviewing everything from their warehouse tech to their shopfront, comparing quotes from suppliers as varied as software vendors and local specialists like Vesta Blinds and Shutters Mansfield as part of a broader capital refresh cycle. The point being that capital planning discipline, whatever the category, is the thing separating businesses that thrive from those that overextend.

    The National Living Wage is not going to stop increasing. UK logistics operators that treat each annual rise as a one-off shock to absorb are already behind. The ones building multi-year automation roadmaps, tying them to realistic payback models and proper change management, are the ones who will still be operating at margin in 2030. The technology is ready. The economics now point clearly in one direction. The question is execution.

    Frequently Asked Questions

    How much does warehouse automation cost for a UK logistics business?

    Costs vary significantly by system type. An autonomous mobile robot fleet for a mid-sized warehouse typically runs from £500,000 to £2.5 million depending on fleet size and site layout. Fixed goods-to-person systems like AutoStore grids can cost considerably more. A new warehouse management system implementation adds £150,000 to £500,000 on top, depending on complexity and integration requirements.

    Is warehouse automation actually cost-effective given the National Living Wage increases?

    For many UK operators, yes. The payback period on automation investment has shortened considerably as the NLW has risen. A project that looked like a six-year return in 2022 can now model closer to three years for a business with high pick volume and stable order profiles. The calculation depends heavily on throughput, order consistency, and how well the business defines its requirements before committing.

    What types of warehouse automation are UK fulfilment businesses investing in most?

    Autonomous mobile robots are the fastest-growing category among mid-market operators because they are flexible and do not require structural warehouse changes. Goods-to-person systems using cube storage or conveyor sorters are popular at larger sites. Warehouse management system upgrades and AI-driven slotting and forecasting tools are being deployed alongside physical automation at most serious operations.